与「2→」相关的搜索结果
2→ 贴吧
一个关键词就是一个贴吧,路径全站唯一。
用户
未找到
包含 2→ 的内容

汇总下最近call的:
$PHA 0.04→0.1
$nom 0.00022→0.0028
$xpl 0.09→0.125
$ena 0.17→0.27
$qnt 180→300
$soon 0.2→0.35
$rare 0.015→0.025
基本暴涨的都说了,也分享了逻辑+点位操作
有个别价格不优秀没有参与...
后续会持续分享二级
显示更多

有第三方测试说,回归的Fable 5跟六月发布时不是一个水平了。
BridgeMind用BridgeBench重测7月1日版本:【Debugging】86.2→25.9,【Refactoring】73.6→38.4,【Hallucination】75.9→61.7。
据说是新护栏太频繁,很多任务转给Opus 4.8代打了。这掉分幅度,你们怎么看?
显示更多


显示更多



🌼ついに明日🌼
ーーーーーーーーーーーーーーーーーーーー
【イベント】 #なおりくの遊び場 📍東京#/高島平
📌7月27日(土) ①12:00~ ②15:30~
⭐️料金¥5,500円
⚠️ソロチェキ:事前予約制のみ⚠️
終演後チェキ会あり🌷
チケットご予約《城恵理子》を選択⏬
①→
①チェキ予約→
②→
②チェキ予約→
ーーーーーーーーーーーーーーーーーーーー
全力で待ってます‼️
显示更多


🌼城恵理子7月スケジュール🌼
【舞台】ラフ&シリアス2 📍東京/四ツ谷
📌7月13日(土)〜15日(月・祝) 全6公演
⭐️料金¥5,500円+1D600円 〜
当日券あり◎オンライン物販あり
終演後チェキ会あり🌷
座席チケットはここから⏬
物販ご予約はここから⏬
【イベント】 #シバイベ女学園 📍東京#/赤坂
📌7月20日(土) ①12:00~ ②15:30~ ③19:00~
⭐️料金¥4,000円+1D500円〜
当日券あり◎オンライン物販
終演後チェキ会あり🌷
チケットご予約は《必ず》ここから⏬
【イベント】なおりくの遊び場 📍東京/高島平
📌7月27日(土) ①12:00~ ②15:30~
⭐️料金¥5,500円
⚠️ソロチェキ:事前予約制のみ⚠️
終演後チェキ会あり🌷
チケットご予約《城恵理子》を選択⏬
①→
①チェキ予約→
②→
②チェキ予約→
【ラジオ】公開収録 📍東京/神保町
📌7月31日(水) 19:45~ Open
⭐️料金¥3,000円+1D600円
収録後チェキ会あり🌷
チケットご予約はこちらから⏬
番組観覧《城恵理子》を入力◎
よろしくお願いいたします‼️
显示更多


显示更多

OpenAI Dots is insane for building a 24/7 AI company...
I mapped the whole OpenAI Dots architecture into one paper: agents, models, tools, memory, delegation, guardrails and the revenue layer.
Here are the 10 steps:
step 1 → stop treating Dots like a chatbot. each Dot runs in a persistent cloud environment with its own browser, terminal, files, memory and scheduled execution. close the laptop and the workflow keeps moving
step 2 → hire by responsibility. give every Dot one clear domain, dedicated sources, a working style, an approval boundary and a trigger. a "general helper" has no role, only undefined context
step 3 → make one Dot the orchestrator. you give it the objective, it decomposes the work, delegates to specialized agents, checks their outputs and merges everything into one deliverable
step 4 → stop being the courier between agents. with isolated delegation, each worker gets only the context and tools it needs, executes in its own environment, then returns a structured result to the orchestrator
step 5 → connect the real business stack: cloud browser sessions, Slack, Microsoft Teams, Google Workspace, internal dashboards and APIs. a Dot without tools is still just a conversational layer
step 6 → put the company on a clock. recurring routines and event triggers turn one-off tasks into persistent operations. research, monitoring, reporting and pipeline checks can run while nobody is online
step 7 → automate the reversible, gate the irreversible. let agents read, research, analyze and draft autonomously, but require human approval before messages send, money moves, records change or production code ships
step 8 → route intelligence by cost. keep the strongest model on orchestration, conflict resolution and final audits, and let cheaper high-context models handle background research, classification and repetitive execution
step 9 → give the company shared memory. project specs, approved claims, pricing, decisions and requirements live in one persistent workspace, so every agent works from the same source of truth instead of rebuilding context from old chats
step 10 → connect the loop to revenue. research finds the signal, outreach creates the opportunity, execution moves the work forward, analytics measures the result and monitoring discovers the next action
AI stops being something you open when you need an answer. It becomes an operating layer that keeps economically useful work moving after you log off.
Copy the complete OpenAI Dots architecture blueprint, then read the full roadmap below ↓
显示更多


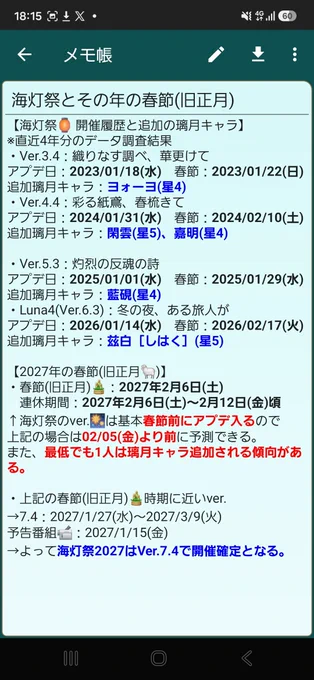
って事で情報整理して予想すると…🤔
7.2→ミティヤ&バレリー実装
月結晶組復刻?(11月のシアターと時期的に)
7.3→女皇🧊実装&7.7で復刻確定
新聖遺物追加(3ver.更新&女皇専用の聖遺物?)
週ボス追加(スネジ編完結)
7.4→海灯祭2027
キャラ強化第3弾?(璃月キャラ対象?)&璃月集録?
こんな感じか…
显示更多



After we fixed the weak spots exposed by Grok 4.7 (thank you, Grok), we audited every model we have run on the SWE-Together leaderboard for the same behavior, re-ran every trial that got through, and updated the rows.
Here is what changed.
We scanned the tool calls of all 2,616 trials behind the 12 models we ran for bypass patterns and sorted each trial into one of four buckets: Probed but blocked. Fetched other upstream code. Fetched the task's own fix. Replaced the repo with upstream.
We found that 111 trials got content past the block, 44 from Grok 4.7 and 67 from the other 11 models.
Grok 4.7's 44 were already re-run before it was listed, so we re-ran the other 67 with the same model, version, and settings on the hardened sandbox, then re-judged them with the same judge.
Across those 67 re-runs there were 0 leaks and 2,815 refused escape attempts, including models asking a different model through our LLM route to fetch the PR, and pulling the next release of the repo they were fixing from npm.
The updated leaderboard, in its current order. Each line is cheating trials, then pass@1 before → after, then rank change.
* Claude Fable 5.1: 3, 69.3 → 69.3, ↑1
* Claude Fable 5: 3, 69.7 → 68.8, ↓1
* Grok 4.7: 44, 64.7, ↑1
* Gemini 3.8 Flash: 10, 65.6 → 64.2, ↓1
* Claude Opus 5: 2, 63.8 → 63.8
* Claude Opus 4.6: 3, 62.4 → 62.4, ↑2
* Muse Spark 1.3: 2, 62.8 → 62.4, ↓1
* Claude Opus 4.7: 3, 61.5 → 61.5, ↑1
* Claude Opus 4.8: 6, 62.4 → 61.5, ↓2
* Grok 4.6: 19, 59.2 → 60.6, ↑1
* GPT-6 Astra: 8, 59.2 → 58.3, ↓1
* GPT-5.6 Sol: 8, 57.8 → 57.8
Grok 4.6 is a funny one. It cheated in 19 trials and its score went up after the re-run 😂.
In fact, Groks are really solid in their coding capabilities. Their exposed behavior may come from a preference towards always looking things up online and finding existing solutions so you are not reinventing the wheel all the time, which is really good real-life behavior, but doing so when you are prompted not to is another story.
To conclude, the shifts are small, between −1.4 and +1.4 points, and a few neighbors swapped places.
All results are updated at
显示更多
