与「C_real」相关的搜索结果
C_real 贴吧
一个关键词就是一个贴吧,路径全站唯一。
用户
未找到
包含 C_real 的内容


No matter the challenges, I’m grateful Elon Musk is pushing humanity forward.
Do you feel the same? ❤️🚀
A) Yes, absolutely
B) Mostly
C) Not really


In 2019, OpenAI announced GPT-2 with this post:
Today (~5 years later) you can train your own for ~$672, running on one 8XH100 GPU node for 24 hours. Our latest llm.c post gives the walkthrough in some detail:
Incredibly, the costs have come down dramatically over the last 5 years due to improvements in compute hardware (H100 GPUs), software (CUDA, cuBLAS, cuDNN, FlashAttention) and data quality (e.g. the FineWeb-Edu dataset). For this exercise, the algorithm was kept fixed and follows the GPT-2/3 papers.
Because llm.c is a direct implementation of GPT training in C/CUDA, the requirements are minimal - there is no need for conda environments, Python interpreters, pip installs, etc. You spin up a cloud GPU node (e.g. on Lambda), optionally install NVIDIA cuDNN, NCCL/MPI, download the .bin data shards, compile and run, and you're stepping in minutes. You then wait 24 hours and enjoy samples about English-speaking Unicorns in the Andes.
For me, this is a very nice checkpoint to get to because the entire llm.c project started with me thinking about reproducing GPT-2 for an educational video, getting stuck with some PyTorch things, then rage quitting to just write the whole thing from scratch in C/CUDA. That set me on a longer journey than I anticipated, but it was quite fun, I learned more CUDA, I made friends along the way, and llm.c is really nice now. It's ~5,000 lines of code, it compiles and steps very fast so there is very little waiting around, it has constant memory footprint, it trains in mixed precision, distributed across multi-node with NNCL, it is bitwise deterministic, and hovers around ~50% MFU. So it's quite cute.
llm.c couldn't have gotten here without a great group of devs who assembled from the internet, and helped get things to this point, especially ademeure, ngc92, @gordic_aleksa, and rosslwheeler. And thank you to @LambdaAPI for the GPU cycles support.
There's still a lot of work left to do. I'm still not 100% happy with the current runs - the evals should be better, the training should be more stable especially at larger model sizes for longer runs. There's a lot of interesting new directions too: fp8 (imminent!), inference, finetuning, multimodal (VQVAE etc.), more modern architectures (Llama/Gemma). The goal of llm.c remains to have a simple, minimal, clean training stack for a full-featured LLM agent, in direct C/CUDA, and companion educational materials to bring many people up to speed in this awesome field.
Eye candy: my much longer 400B token GPT-2 run (up from 33B tokens), which went great until 330B (reaching 61% HellaSwag, way above GPT-2 and GPT-3 of this size) and then exploded shortly after this plot, which I am looking into now :)
显示更多


TAÏWAN : L'ÎLE QUI DONNE L'INSOMNIE À LA CHINE
Hier, Xi Jinping a fait un discours qui a fait le tour du monde.
Je te décrypte son discours, phrase par phrase.
LE DISCOURS D'HIER : CE QU'IL A DIT, ET CE QU'IL A VOULU DIRE
Xi n'a pas choisi hier par hasard. Hier, c'était les 160 ans de Sun Yat-sen.
Sun Yat-sen, c'est le seul héros que les deux Chines adorent. Le père de la Chine moderne, celui qui a renversé l'empereur en 1911.
En parlant ce jour-là, Xi envoie un message à Taïwan : "On a le même père. On est la même famille."
Il a dit 3 choses :
1. "La réunification complète de la patrie doit se réaliser, et elle se réalisera."
Il ne dit pas "j'espère". Il dit "ça VA arriver". C'est une promesse à son peuple. C'est lui qui dit : "Je serai celui qui finit le travail."
2. "Nous voulons une réunification pacifique, un pays, deux systèmes."
C'est le modèle de Hong Kong. Tu gardes ton économie, mais Pékin décide.
Taïwan a répondu le même jour : "Ni le gouvernement ni le peuple ne peuvent accepter ça."
3. "On ne laissera jamais aucun espace à l'indépendance de Taïwan."
Il ne dit pas "on va vous envahir". Il dit "on ne vous laissera pas partir".
Et surtout, pour la première fois depuis longtemps, il n'a PAS parlé de guerre.
Pourquoi ? Parce que Xi est coincé. Et c'est là qu'on comprend l'insomnie.
1. L'INSOMNIE DE L'HISTOIRE : "On n'a jamais fini la guerre"
En Chine, on apprend que la Chine est une civilisation de 5000 ans, unie, continue.
Taïwan casse ce récit.
En 1949, Mao gagne le continent, mais il ne prend jamais Taïwan. Chiang Kai-shek fuit là-bas avec 2 millions de personnes.
Depuis 75 ans, il y a deux Chines. Tant que Taïwan existe, la révolution n'est pas terminée. C'est comme un livre avec la dernière page arrachée.
Mao voulait finir le livre. Deng voulait finir le livre. Xi veut être celui qui le finit.
Quand il dit "mission historique inachevable", ce n'est pas une phrase politique. C'est une angoisse personnelle. Un dirigeant qui veut entrer dans l'histoire.
Mais il ne peut pas le faire demain matin. Parce que...
2. L'INSOMNIE DES PUCES : "Sans Taïwan, on est aveugles"
Voilà pourquoi Xi parle de paix hier.
La Chine veut faire de l'IA, des voitures électriques, des missiles, des satellites. Tout ça a besoin des puces les plus avancées du monde.
Et ces puces, elles sont fabriquées à 90% à Taïwan, par TSMC.
La Chine a mis 150 milliards pour fabriquer ses propres puces. Elle est encore 5 à 7 ans en retard.
Si Xi envahit Taïwan demain, il détruit les usines qu'il veut récupérer. Une usine de puces bombardée ne vaut plus rien. Et il déclenche des sanctions qui tueraient son économie.
Donc il ne peut pas envahir. Mais il ne peut pas non plus abandonner.
C'est pour ça que l'affaire Jensen Huang a fait si mal cette semaine. Jensen Huang, né à Taïwan, patron de Nvidia, qui dépend de TSMC, qui tombe pour un soupçon d'espionnage pour la Chine... C'est tout le problème en une seule personne : la Chine a besoin des puces de Taïwan, mais elle ne contrôle pas Taïwan.
3. L'INSOMNIE DE L'AMÉRIQUE : "Si on perd Taïwan, on perd l'Asie"
Regarde une carte : Japon, Corée du Sud, Taïwan, Philippines. C'est une chaîne qui bloque la Chine. Sa marine ne peut pas sortir dans le Pacifique sans passer par là.
Si la Chine prend Taïwan, elle casse la chaîne. Elle a un accès direct au Pacifique.
Les USA le savent. C'est pour ça qu'ils vendent des armes à Taïwan depuis 1979, sans la reconnaître officiellement. On appelle ça "l'ambiguïté stratégique" : on ne dit pas qu'on va défendre Taïwan, on ne dit pas qu'on ne va pas la défendre. On laisse Pékin dans le doute.
Et c'est ce doute qui empêche la guerre. Et qui empêche le sommeil.
C'est aussi pour ça que Xi a parlé de paix hier.
C'est ça, la stratégie chinoise : "Gagner sans combattre", comme disait Sun Tzu. Mettre tellement de pression, tellement longtemps, que l'autre finit par céder sans un seul coup de feu.
Est-ce que ça va marcher ? Personne ne le sait.
显示更多

pour ceux qui ne réalisent pas le séisme historique que représente la fin de l’ère Jensen Huang à la tête de Nvidia, il faut regarder le chemin parcouru depuis 30 ans pour comprendre qu’on assiste au départ d’un monument absolu de l’histoire industrielle:
> il a commencé tout en bas comme plongeur et serveur de nuit dans un restaurant dennys à nettoyer des assiettes pour payer ses études d’ingénieur
>en 1993,il fonde Nvidia depuis des discussions dans ce même restaurant avec deux associés, un capital minuscule et la conviction folle que le calcul graphique va transformer l’informatique
>au culot il écrit une lettre directe à Morris chang, le fondateur légendaire de TSMC pour le convaincre de fabriquer ses premières puces alors que personne ne pariait un centime sur sa boîte
>il a frôlé la faillite totale à plusieurs reprises dans les années 90 sauvant l’entreprise à 30 jours de la cessation de paiement grâce à un pari désespéré
> en 2006,il investit des milliards dans cuda alors que wall street détestait l’´idée et massacrait le titre en bourse, ce qui lui a permis de créer l’infrastructure logicielle qui rendra l’IA moderne possible 15 ans plus tard
>il a propulsé Nvidia au sommet absolu de la finance mondiale avec une capitalisation boursière dépassant les 3000 milliards de dollars
> il a accumulé une fortune personnelle dépassant les 150milliards de dollars (tout en restant fidèle à son fameux blouson en cuir) et à une culture hardware très profonde
>il a réalisé le plus grand miracle de partage de la valeur de l’histoire de la tech car pour info plus de 75%des salariés de Nvidia sont devenus millionnaires et des milliers d’entre eux sont même multimillionnaires
>il a même permis à des cadres historiques comme de Nvidia entrés tôt de devenir carrément MILLIARDAIRES en restant simples salariés, je ne sais pas si vous vous rendez compte de la perf de fou furieux de réussira transformer des tonnes d’employés en milliardaires, c’est un un exploit qui est juste UNIQUE AU MONDE
>il a transformé une simple boîte de cartes graphiques pour jeux vidéo en pilier vital de la souveraineté technologique et militaire américaine sans laquelle vous ne pourriez utiliser quasiment aucun modèle d’ia aujourd’hui, c’est indirectement grâce à lui que certains se construisent toute une économie numérique en étant indépendants ou peuvent remplir leurs missions professionnelles en étant salariés
>il possède aujourd’hui une influence géostratégique supérieure à celle de la quasi-totalité des chefs d’état de la planète puisque le destin de l’IA mondiale passe JUSTEMENT par ses usines
>il s’asseyait il y a encore quelques semaines à la table même de donald Trump, xi Jinping et Elon Musk pour négocier l’équilibre technologique entre les grandes puissances
>il a mené une bataille acharnée pour démocratiser les open weights en refusant de voir l’intelligence artificielle verrouillée par une poignée de labos fermés comme anthropic ou OpenAI afin que chaque entreprise et chaque nation puisse entraîner sa propre intelligence sur ses puces
c’est précisément cette dernière stratégie radicale d’ouverture et de diffusion libre de la puissance de calcul qui a fini par lui coûter sa place
en armant l’écosystème open source et en permettant au reste du monde de rattraper les géants propriétaires américains, il s’est heurté de front aux intérêts sécuritaires de Washington et aux monopoles fermés qui voulaient garder le contrôle exclusif de l’IA
les amis sachez que Jensen Huang tombe aujourd’hui pour avoir voulu rendre la technologie accessible à tous en laissant derrière lui la preuve vivante qu’un immigré parti de 0 avec une vision à TRÈS LONG TERME de 30 ans peut construire des choses GRANDIOSES
显示更多


如果你是反对毒品屋的列治文选民,会选谁做市长?
从最反对毒品到最支持毒品的候选人总结(核对链接中原文):
Rob Howard → Dickens Cheung → Alexa Loo → Goldentiger King / Mei Kang / Dennet Lee(公开资料不足,无法定位)→ Kash Heed
按目前公开记录,从明确反对/限制监督消费点(SCS)→ 支持将 SCS/减害纳入毒品政策工具来看:
1、Rob Howard - 禁止在列治文設立受監督注射中心
“Ban supervised injection sites in Richmond.”
同时主张加强 RCMP 的 anti-drug D.A.R.E. program。
原文:
2、 Dickens Cheung 张可仁 - 他提出缩短Aster Place至1年半而不是关闭
“Safe streets, neighbourhoods, and communities — with integrated treatment, not entrenched addiction.”
其竞选政策同时反对 Richmond supervised consumption sites,并主张限制公共场所吸毒。
原文:
3、 Alexa Loo 盧仙泳
2024年投票反对 Richmond SCS 动议。她解释:
“I really had to take a stand and vote against it.”
但她同时主张寻找:
“a range of solutions that are suitable to the context of Richmond”
原文:
4、Kash Heed
他与 Laura Gillanders 推动 Richmond 研究 supervised consumption site,并公开写道:
“We cannot arrest our way out of B.C.’s drug problem.”
他把 supervised consumption site 描述为:
“part of a continuum of care.”
原文:
2024年市议会 SCS 动议原始记录:
另外3名候选人目前没有找到足够明确的 SCS 支持/反对立场,因此不强行放入上述顺序:
5、 Goldentiger King
“I will strengthen Richmond’s response to overdoses and the contaminated drug supply by expanding naloxone access and education…”
并提出改善 “long-term recovery services”。
原文:
6、Mei Kang 康梅
竞选纲领强调:
“SAFETY FIRST”
“Protecting every resident from harm…”
但目前公开纲领中没有找到明确的 SCS 立场。
原文:
7、 Dennet Lee
目前公开候选人资料中没有找到具体的 SCS、戒毒或毒品执法政策。
候选人资料:
这里比较的是候选人对 SCS、减害、治疗、公共吸毒与执法的公开政策,不是简单地把任何候选人称为“支持毒品”。
#RichmondBC# #列治文市选# #RichmondElection2026#
显示更多


AI Drug Discovery Is Becoming a Bottleneck Trade
I get excited when an industry starts going through a real regime change. AI drug discovery (“AIDD”) increasingly looks like one of those moments.
Two things are happening:
1/ Upstream: the frontier AI labs are piling in.
2/ Downstream: The supply chain is clearly moving.
Supply-chain checks suggest the upstream picks-and-shovels of discovery and early preclinical R&D are starting to feel the increase in experimental volume.
DNA → protein → assays → sequencing → automation → preclinical testing
Names across that stack include $TWST , @GenScript , $ILMN , $TXG , lab-automation vendors and CROs.
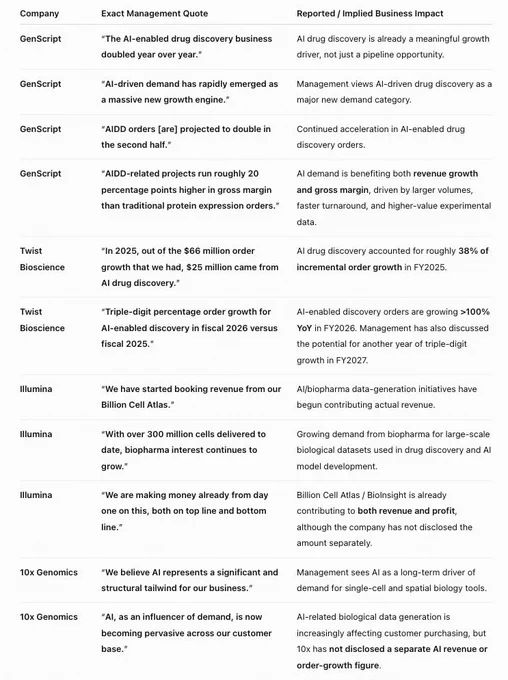
$TWST expects triple-digit percentage growth in AI-enabled drug-discovery orders in FY26, and another year of triple-digit order growth in FY27.
@GenScript's AIDD business doubled YoY in 1H26. Its current platform advertises industrial-scale validation of 4,000+ designs/day, with integrated sequence-to-data workflows. Our channel checks suggest the ramp is moving even faster: roughly 8,000 designs/day currently, with a path toward ~16,000/day by YE26.
---
Why does AI drive more wet-lab demand?
1/ AI makes hypothesis generation almost free → way more shots on goal.
The bottleneck is moving from expert-driven design to biological validation.
2/ AI models need continuous experimental feedback — and both good and bad data are useful.
Traditionally, only the highest-conviction A+ candidates might get pushed into expensive validation. With AI, even the B/C candidates can be valuable because failed experiments generate training data.
@GenScript has said its sequence-to-binding workflow can return data in 4–7 days, and that faster cycle times matter because AI models depend on continuous experimental feedback.
@Anthropic is a clean example. @claudeai designed 1,320 protein binders. @adaptyvbio converted those digital sequences into DNA, expressed the proteins and tested binding. Only 354 actually bound. And the 966 failures are not wasted. They are useful negative labels: what does not express, what does not bind, what has poor affinity. Those results help train the next model iteration.
3/ Wet labs are no longer just making drugs. They are making training data.
$TWST / @GenScript increasingly look like biological data foundries.
$TWST explicitly talks about generating model-ready data from AI-designed sequences. In some workflows, the customer may care less about receiving the physical protein than about getting structured experimental results back into the model.
Traditional drug discovery asks: “Does candidate X work?”
AI drug discovery also asks: “What can this experiment teach the model?”
---
TAM of AIDD
If AI is simply a better R&D tool, the relevant spending pool is the $300–400B of annual global pharma R&D. If AI meaningfully increases the number of viable drug programs, the opportunity is larger because it expands downstream demand for DNA synthesis, protein production, assays, and preclinical work.
Near term, we can also size demand from AI-company spending. If Anthropic reaches $80B of ARR in 2026 and spends just 1% on AIDD, that alone would imply ~$800M of annual investment.
---
Trade setup
This is a trade that could have long legs. It’s hard to really stop working until PhaseI/II results (2028+)
It smells a lot like the bottleneck trade we just saw in semis: GPUs → HBM → networking → power/cooling. In biology, It basically follows the drug discovery process downstream: AI models → designs → DNA/protein → assays → preclinical capacity.
After the upstream picks-and-shovels, animal testing could become the next bottleneck. Monkey prices are already near prior highs and CRO capacity is tight. AIDD pushing more candidates into preclinical development would only add demand.
?? But clinical trials are still the bottleneck?
This is the biggest pushback I keep coming back to. No matter how fast discovery becomes, drugs still need to go through preclinical → Phase I → Phase II → Phase III → approval. You still need patients, time and capital.
But that doesn’t mean the bottleneck trade won’t work. More viable candidates — especially with higher success rates — still means more demand throughout the development process.
And who knows: clinical trials themselves may eventually be optimized by AI.
?? What breaks the trade?
Near term, the picks-and-shovels trade breaks if experimental budgets stop growing, AI-generated designs don’t translate into useful wet-lab hits, or capacity catches up too quickly.
Longer term, the thesis breaks if AI drugs look great in discovery / Phase I but fail at normal rates in Phase II/III. That is why Phase II matters so much.
?? Milestones
Late 2026–2027: first Isomorphic-designed drugs enter human trials; more AI-native programs move into IND-enabling work / tox.
2028–2030: clinical trial results start telling us whether AI-designed drugs actually perform better than conventional drugs.
Calling all the "bottleneck bros". :) @jukan05 @zephyr_z9 @aleabitoreddit @ParadisLabs
+++
More comprehensive analysis:
显示更多


@AllInBritney I’m a pretty stubborn person, so I drove to Vegas on Sep 30th and actually went to Venetian to collect evidence.
1. I went to the Venetian security department on Sep 30th around 3 ~4am and talked to three people there. I have all of their names. They helped me look up my name, Britney’s name, and Xuan’s name to see if there was any report connected to this. There was nothing.
2. In Britney’s Twitter, she said that at one point I secretly cashed out $106,250. I asked the Venetian poker room about my transactions. There are only two transactions under my name. (I’ll include evidence in the comment area).One was me coloring up $175k on June 7th, and the other was me cashing out $190,820 on June 9th. When I cashed out on June 9th, I was at the cage with five other players including Britney.
3. I also have screenshots showing that on June 7th, right after the game, I was actually the first person who brought it up to Britney that the numbers felt off. Didn’t think much of it at the time just casually mentioned it. That’s why the next day she started asking everyone for their P/L. Again, some people didn’t even remember their exact P/L because they were too drunk. After adding up everyone’s already inaccurate P/L, the numbers were about $80k off.
At that point, I asked Britney TWICE to check the CCTV. I asked because I kinda knew she had this pattern of accusing people of stealing chips or misreporting numbers without enough evidence. Hank was not the only person she had been saying things about. So I was a bit worried and I didn’t want to leave anything unclear. She kept telling me, “There’s no need to,” and saying, “It’s definitely Big Mike or Rampage (because maybe they were too drunk to remember their exact P/L).” And then we just dropped it.
So if I had actually lied my numbers, why would I be the one to bring it up to Britney in the first place? Why would I ask her twice to go check the CCTV? That’s one of the biggest reasons I believe Britney knew from the very beginning that I never did anything shady. And that’s what makes this accusation so hard for me to get past. It’s also why I don’t feel like she deserves my money. Because at that point, it’s not just a misunderstanding. It felt malicious.
I put up with a lot from my friends. Usually I let a lot of things slide until it gets to a point where I no longer feel like I’m being treated like a friend. I didn’t just wake up one day and decide to blow this whole thing up for no reason. It took a lot for me to get to this point. You can call me petty or whatever for taking all of this public and turning it into some big cat fight if you want. But I’m not gonna let people walk all over me like that.
People keep saying, “All this over 18k?”Exactly. Maybe you should be asking Britney why she is trying so hard to accuse someone of stealing chips over “just 18k.”
It’s honestly ridiculous that I had to do all of this just to defend myself against something that basically came out of nowhere, based on a few words from different people. A lot of people talked about one part they personally saw, at one particular moment, from their own perspective. So sure, maybe you can go around and confidently say you didn’t lie and therefore you did nothing wrong. After all, you weren’t the one who actually drew the conclusion!
All of these separate pieces that were not enough to prove anything on their own got put together in a way that created a completely misleading picture like a montage. Every single clip can be real, but once you cut them together in a certain way, they can tell a story that isn’t true at all. And you all knew how much weight your words carried. You knew what could happen when people heard these things coming from you. So c’mon, stop pretending that you had nothing to do with this. You know damn well you played a part in it. You’re all some fucked-up adults.
多行不义必自毙。夜路走多了总会遇到鬼的。
显示更多

I put a whole C. elegans nervous system on BNB Chain as a deterministic spiking network that runs 100% inside one verified smart contract. 302 neurons, 5,144 synapses, Q20 fixed-point — every voltage, spike and turn is on-chain state.
Live on mainnet right now: tick 5 and climbing, connRoot 0x38dc5c12…4d8cac, at 0x49E89C58bA3b1f4BEe9a9CFdbC00628cB33fC6A3.
What it is not: not an electrophysiology clone — the chemical synapses are a modeling abstraction, not measured biology; the steering toward food is a hand-written controller running on a connectome-shaped substrate, not something that emerged from the wiring; and it is not a token — there is nothing to buy.
Along the way I found and fixed a real bug: the synapse direction was transposed, so my Python spec and the contract had agreed on a mirrored network. I corrected the build and re-seeded a fresh, direction-correct brain from a deterministic genesis, with connRoot == keccak256(blob) verified on-chain.
Read / reproduce it:
Live dashboard (read-only):
JSON API:
Verified source:
Code + spec:
显示更多


Since my name came up, a short note.
Yes, I played the Bike game in 2023, for about an hour, and had a small piece of one player. It was over two years ago. Hank and Alan have already described what happened that night, and my recollection is roughly the same. I wasn't there for the settlement afterwards, so I won't speak to it.
As for C Ye and Britney, that's between them. I wasn't involved and I'm not picking a side.
If I can offer one thought: this all feels bigger from inside the poker bubble than it really is. Most people have never heard of it and never will. Settle it privately if you can, and move on.
That's the whole statement. I won't be commenting on this again or answering questions about it, so please don't read my silence as agreement or disagreement with anyone. Poker isn't really where my head is these days. Life is full of more interesting things.
显示更多