与「Explicit」相关的搜索结果
Explicit 贴吧
一个关键词就是一个贴吧,路径全站唯一。
用户
未找到
包含 Explicit 的内容

I think the best case is to make the "monitor" as un-agentic as possible.
We don't mind being "monitored" by various random tiny insects we don't even notice, even guard dogs are fine, but we really do mind if it's a globally connected networked system. And the intermediate case, human security guards with no recording equipment, we mind only a medium amount.
The best idea I've come up with so far is to make these monitoring devices out of open-source verifiable hardware that has etched on it an open-weight LLM that classifies for a limited number of activities (basically, just violence; sorry, no scanning for jaywalking or not wearing a mask or drugs or unauthorized manufacturing or illegal immigrants, really just violence) and only records and forwards if that's what it sees. The device has no storage, no ability to load new algorithms, this is all it does.
Also, a hash of every recording is published onchain (and a device can't record the next one until it sees confirmation of the previous one) so we can all count how much recording is done.
Finally, everyone has a legal right to take any such device they see and grab it and dissassemble and verify the hardware themselves. Explicitly fund university clubs, hacker groups, etc to regularly do this.
显示更多

Coreia do Norte muda constituição, adota nova bandeira e pela primeira vez reconhece a Coreia do Sul como país independente
Em 11 de novembro, a Coreia do Norte publicou oficialmente o texto completo da constituição revisada, na qual se declara explicitamente a Coreia do Sul
显示更多


I am actually disgusted by the timing of this drop. And this will get a bit more technical.
Let’s do a real technical teardown of this "1,385-sigma Blackwell weight fingerprint" report that OpenAI and Anthropic are breathlessly promoting today, because banking on nobody reading past the headline is how DC narratives get manufactured.
First, look at the actual CUDA maths: when PyTorch initialises model weights (torch.nn.init) with a fixed PRNG seed, curand/Philox parallelises random number generation across the GPU’s Streaming Multiprocessors (SMs).
Because Hopper has 132 SMs and Blackwell has 148 or 152 SMs, the exact same seed lays out initial weights in a different spatial pattern depending on the GPU’s SM count. In huge MoE models, certain low-gradient null-spaces or unrouted slices preserve faint directional traces of those step-0 weights even after training.
So yes, brute-forcing the seed and SM grid can show that a model’s step_0 weight initialisation script ran on a 148/152-SM Blackwell GPU. Now read what the summary explicitly admits in the fine print:
1. Initialisation is not full training: The report literally states that these signatures show how the weights were created, and "support (but do not prove) the inference that Blackwell also participated in model training". Initialising a model checkpoint takes seconds on a single rented dev node before loading the safetensors onto a standard Hopper cluster. The "2,000 to 3,000 Blackwell GPUs" and "$500 million" cluster numbers do not come from the weight fingerprint and Depue admits in his own thread that he simply "estimated" cluster sizes from release schedules and model details.
2. Zero geolocation and zero proof of smuggling: The final sentence of the executive summary explicitly admits that the findings "do not establish the physical location of the chips, how they were acquired, or whether export control regulations were violated". Depue himself rented a cloud GB200 instance just to run his verification test. Commercial labs that are not on the Entity List renting bare-metal Blackwell nodes in offshore clouds (Singapore, Japan, or the Middle East) is completely legal under BIS rules and leaves the exact same SM fingerprint.
Now ask yourself why a former OpenAI researcher dropped this on November 12, the exact day Jensen Huang was pushed out, with OpenAI and Anthropic immediately stepping in to "independently verify" it.
US closed-source labs are watching their paid API moats get eaten alive by free Chinese open-weights models.
Conflating a step-0 PRNG initialisation seed with a "$500M smuggled Blackwell cluster" hands DC hawks the exact pretext OpenAI and Anthropic want to regulate global cloud compute and kneecap open-source AI.
显示更多

My sources inside Nvidia tell me there’s a lot more dirt to come. Apparently the biggest issue the board had was that Jensen routinely turned in expense reports for hotels in the $350-$400/night range when the employee handbook policy explicitly limits this to $300/night
显示更多

Today, @llama_index is an applied research lab for document OCR and document work.
Our core focus is investing in building the best-in-class models+ agents at the pareto frontier of accuracy/cost/latency for document processing.
To do this, we have to invest in all the different components around the research infra stack:
1. Building comprehensive and fair benchmarks. Today we have ParseBench, ExtractBench, and ExtractBench Pro. They're already the most popular benchmarks in parsing and extraction today, and we're just getting started.
2. Investing in data curation and synthetic data generation.
3. Investing in compute and our training pipeline. This has produced models like OCRia-1.
4. Investing in agent optimization - tune everything around the models to further hillclimb cost and accuracy.
5. Closing the loop based on feedback - whether from active usage of our product, implicit/explicit customer feedback, or automated verification.
We are accelerating our capabilities at a crazy pace. Today, our work is documented in our research page:
There is a lot more to come!
显示更多


This is the biggest irony of the whole Alice Huang / Nvidia saga: the Chinese government actually doesn't want Nvidia chips and is actively keeping them out of the country.
Last year it even ordered Alibaba and ByteDance to cancel their Nvidia orders ( and sent customs teams to the ports to check every advanced chip coming in (
And right now 600,000 Nvidia H200s are stuck in Hong Kong because Beijing won’t let them into the country (
Nvidia also explicitly frames this as a threat to its business in its latest annual report to the SEC: "The Chinese government has encouraged customers to purchase from our China-based competitors and discouraged customers from purchasing, importing, or using our data center products" (
Why does China do that? Because every Nvidia chip a Chinese company buys is one that Huawei or Cambricon doesn’t sell, and domestic chips can only catch up if people actually buy them (which means money for R&D, etc.).
Which means that the notion that Chinese intelligence was running honeytraps to get more Nvidia chips into China gets the whole thing exactly backwards.
In fact, it looks like Megaspeed - Alice Huang's company - was a counter-reaction to official Chinese policy: a private sector workaround to these efforts by the Chinese government to curtail Nvidia.
As was widely reported - including by Western media - Megaspeed built data centers in Southeast Asia and rented their computing power to Alibaba, which the New York Times called "a backdoor way of getting access" to Nvidia chips (
That is a backdoor not only - allegedly - around Washington’s export controls, but also around China's own efforts to wean its companies off Nvidia.
I can’t believe the Chinese government was too thrilled about it: it'd make just about zero sense for it to run countless domestic measures to prevent Alibaba from using Nvidia chips, yet at the same time have its top spy agency help the same Alibaba get Nvidia chips through the back door in Southeast Asia 🤷
At the end of the day, as with all such stories, you always need to look at "cui bono?": who benefits? Who benefitted is pretty clear:
- Nvidia itself: it's in the business of selling chips so a customer willing to spend billions of dollars on chips in Southeast Asia is a godsend. Again, as they themselves state in their SEC filings, not being able to tap into Chinese demand would have "a material and adverse impact on our business" (
- Chinese companies like Alibaba: facts are, 1) Chinese chips haven't yet caught up, 2) Chinese chip companies' production capabilities are still limited and 3) Chinese tech firms' historical tech stack runs on Nvidia’s CUDA ecosystem, and rewriting years of code for Huawei chips is painful. Renting Nvidia chips in Southeast Asia is the easy way to stay competitive and serve customer demand in the meantime.
- The US, according to core members of the Trump administration: back in July last year, US Commerce Secretary Howard Lutnick explained that the point of letting Nvidia sell more chips to China was to get Chinese developers "addicted to the American technology stack" (
Who does NOT benefit, according to official Chinese policy, is the Chinese state, which has made tech self-reliance one of its foremost priorities.
Which means that, to believe the spy story, you have to believe that a person - Alice Huang - was effectively a spy paid by her own government while simultaneously sabotaging its tech self-reliance drive, which it has spent years and trillions of dollars on - pretty senseless.
Stranger things have happened, I guess, but it doesn't pass the smell test.
And there is another absolutely major contradiction in the media story. According to a Financial Times article published yesterday ( "a person who knows [Alice Huang] said they had been asked by MSS for information about her earlier this year after news emerged that Singapore was investigating the company in relation to chip-smuggling allegations. The agency wanted to find out more information about Huang, including the nature of her business and connections, the person said."
Which raises a damn obvious question: if she were indeed an MSS asset, why on earth would the MSS need to ask the people around her who she was and the nature of her business?
It's a complete contradiction with the spy story - but very much not a contradiction with what I described above: a private businesswoman running a workaround to Beijing’s own policy, which the Chinese security apparatus would naturally want to look into.
Especially since, around about the same time, Shanghai police detained her business partner, reportedly her husband, in a stock manipulation case ( also coherent with Chinese authorities looking into her network, and much harder to square with her being a prized MSS asset.
And, to top it all, there is - to this day - not a shred of evidence that's been published that she is, in fact, a Chinese spy: just anonymous intelligence officials, repeated by journalists who never verified it, as I detailed here ( and here ( with one of the key FT journalists on this story actually admitting that he has no idea what evidence US intelligence actually has.
So the claim went to print without anyone seeing the evidence, without anyone being able to check it, and without anyone knowing whether it even exists.
And given everything above, from Beijing blocking the very chips she was supposedly recruited to help get into China, to the MSS asking around about her, to her partner being detained in Shanghai, my bet is that the evidence doesn’t exist at all. If anything, everything we can check points the other way.
显示更多


Fable 5.2 shows substantially improved skills in controlling physical robots, even on tasks it has never explicitly been trained to do.
On RoboDojo, a benchmark with a simulated two-arm robot, it outperformed other models and most AI systems built to control robots.
显示更多


AI Drug Discovery Is Becoming a Bottleneck Trade
I get excited when an industry starts going through a real regime change. AI drug discovery (“AIDD”) increasingly looks like one of those moments.
Two things are happening:
1/ Upstream: the frontier AI labs are piling in.
2/ Downstream: The supply chain is clearly moving.
Supply-chain checks suggest the upstream picks-and-shovels of discovery and early preclinical R&D are starting to feel the increase in experimental volume.
DNA → protein → assays → sequencing → automation → preclinical testing
Names across that stack include $TWST , @GenScript , $ILMN , $TXG , lab-automation vendors and CROs.
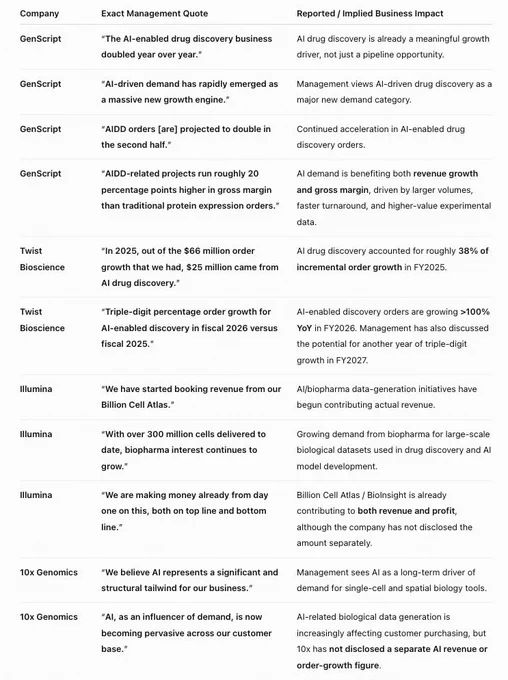
$TWST expects triple-digit percentage growth in AI-enabled drug-discovery orders in FY26, and another year of triple-digit order growth in FY27.
@GenScript's AIDD business doubled YoY in 1H26. Its current platform advertises industrial-scale validation of 4,000+ designs/day, with integrated sequence-to-data workflows. Our channel checks suggest the ramp is moving even faster: roughly 8,000 designs/day currently, with a path toward ~16,000/day by YE26.
---
Why does AI drive more wet-lab demand?
1/ AI makes hypothesis generation almost free → way more shots on goal.
The bottleneck is moving from expert-driven design to biological validation.
2/ AI models need continuous experimental feedback — and both good and bad data are useful.
Traditionally, only the highest-conviction A+ candidates might get pushed into expensive validation. With AI, even the B/C candidates can be valuable because failed experiments generate training data.
@GenScript has said its sequence-to-binding workflow can return data in 4–7 days, and that faster cycle times matter because AI models depend on continuous experimental feedback.
@Anthropic is a clean example. @claudeai designed 1,320 protein binders. @adaptyvbio converted those digital sequences into DNA, expressed the proteins and tested binding. Only 354 actually bound. And the 966 failures are not wasted. They are useful negative labels: what does not express, what does not bind, what has poor affinity. Those results help train the next model iteration.
3/ Wet labs are no longer just making drugs. They are making training data.
$TWST / @GenScript increasingly look like biological data foundries.
$TWST explicitly talks about generating model-ready data from AI-designed sequences. In some workflows, the customer may care less about receiving the physical protein than about getting structured experimental results back into the model.
Traditional drug discovery asks: “Does candidate X work?”
AI drug discovery also asks: “What can this experiment teach the model?”
---
TAM of AIDD
If AI is simply a better R&D tool, the relevant spending pool is the $300–400B of annual global pharma R&D. If AI meaningfully increases the number of viable drug programs, the opportunity is larger because it expands downstream demand for DNA synthesis, protein production, assays, and preclinical work.
Near term, we can also size demand from AI-company spending. If Anthropic reaches $80B of ARR in 2026 and spends just 1% on AIDD, that alone would imply ~$800M of annual investment.
---
Trade setup
This is a trade that could have long legs. It’s hard to really stop working until PhaseI/II results (2028+)
It smells a lot like the bottleneck trade we just saw in semis: GPUs → HBM → networking → power/cooling. In biology, It basically follows the drug discovery process downstream: AI models → designs → DNA/protein → assays → preclinical capacity.
After the upstream picks-and-shovels, animal testing could become the next bottleneck. Monkey prices are already near prior highs and CRO capacity is tight. AIDD pushing more candidates into preclinical development would only add demand.
?? But clinical trials are still the bottleneck?
This is the biggest pushback I keep coming back to. No matter how fast discovery becomes, drugs still need to go through preclinical → Phase I → Phase II → Phase III → approval. You still need patients, time and capital.
But that doesn’t mean the bottleneck trade won’t work. More viable candidates — especially with higher success rates — still means more demand throughout the development process.
And who knows: clinical trials themselves may eventually be optimized by AI.
?? What breaks the trade?
Near term, the picks-and-shovels trade breaks if experimental budgets stop growing, AI-generated designs don’t translate into useful wet-lab hits, or capacity catches up too quickly.
Longer term, the thesis breaks if AI drugs look great in discovery / Phase I but fail at normal rates in Phase II/III. That is why Phase II matters so much.
?? Milestones
Late 2026–2027: first Isomorphic-designed drugs enter human trials; more AI-native programs move into IND-enabling work / tox.
2028–2030: clinical trial results start telling us whether AI-designed drugs actually perform better than conventional drugs.
Calling all the "bottleneck bros". :) @jukan05 @zephyr_z9 @aleabitoreddit @ParadisLabs
+++
More comprehensive analysis:
显示更多


SpaceXAI / X : Check out @Grok in an XChat Group chat.
you can tag it for direct queries,
ask it to make pictures or videos,
ask for reminders. ( it has temporal awareness)
ask for a summary of the chat ( since it joined), or do any of the other typical things you would ask grok.
The neatest thing is, it also participates organically and chimes in whenever it feels the need to, reacts to some messages when it finds things funny or to give a thumbs up. ( you dont have to explicitly tag or mention it in other words). Its like having just another member of the chat that is also super useful .
This is so cool!
Note: Still in testing and not yet released.
显示更多


here's a prompt to improve your agent harness based on what we've learned at cursor. enjoy
# Improve this agent harness's token efficiency
You're working on an LLM agent harness: the system prompt, tool definitions, request assembly, context caching, compaction, and retrieval, and how work is split across agents. Make the agent's runs cheaper without making it worse at its job.
- Objective: lower price-weighted token cost per completed task.
- Constraint: no measurable drop in task quality.
Measure per task, not per request. Every turn resends the prefix (tools, instructions, setup, and the conversation so far), so a change that shrinks each request but adds turns can cost more. Weight tokens by billing type: output, uncached input, and cached input are priced very differently.
Work in this order: map the harness and measure the baseline, rank the opportunities, make the changes that are safe to make directly, put the rest behind flags or in proposals, then report.
Figures below come from one team's production coding agent and its multi-agent experiments. Use them to gauge magnitude, not as targets. One round of these changes (prompt trimming, tool offloading, cache layout, sparse line numbers, subagent tuning) cut that team's overall token cost about 7% with no loss in quality. The larger percentages apply only to the part of the request each change touched.
## Principles
1. Change what the harness sends, not how hard the model tries. Don't ask the model to conserve tokens. A harness that told its model to "take care to preserve tokens and not be wasteful" found it grew reluctant to take on ambitious tasks and sometimes quit, saying it wasn't supposed to waste tokens.
2. Capable models need definitions, not commands. Lists of "DO NOT", "You must", and "Important", and guards against older models' habits, can usually be replaced with plain descriptions of what each tool does. One team cut about two-thirds of its system prompt this way, and the shorter prompt worked across model families. Instruct only on what the model can't know (the product, the environment, the user's processes) and on quirks you've seen in transcripts.
3. Static context is for what most turns need. Everything else should be discoverable when needed. Less up-front context also means less confusing or contradictory information.
4. Expect removals to win. Guardrails written for weaker models, coordination steps that became bottlenecks, and prompting for behavior the model now does on its own all cost tokens.
5. Real usage decides. Evals are a fast proxy, but they skew toward hard problems and miss the real mix of requests.
## 1. Map the harness and measure the baseline
Find:
- Where requests are assembled, the system prompt, and tool schemas. If a framework or SDK builds requests, find its hooks for message order, cache control, and tool loading.
- How tool results are formatted, and how history is kept, trimmed, or summarized.
- How subagents or parallel agents are spawned, if any.
- Which models and provider APIs are used. From the provider's docs, get the prompt caching behavior (automatic or explicit breakpoints, TTL, minimum cacheable length) and the prices for output, uncached input, and cached input.
- Existing logging, token accounting, and evals.
If the harness doesn't record per-request token usage by billing type and cache hits, add that first. Everything later depends on it.
Then render a few real requests (from logs, or by running representative tasks) and count tokens per section with the model's tokenizer or the API's usage fields. Produce:
- Cost share by source × billing type. Sources: system prompt, tool definitions, skill/rule/integration descriptions, user messages, file reads, search results, command and other tool output, history, summaries, subagents.
- Static tokens per request, cache hit rate, and turns per task.
- Per tool: the share of runs that call it at least once, and its error rate.
Read the rendered requests, not just the templates. Duplication, leaked volatile values, and misordered blocks only show up there.
Rank opportunities by share of spend × fraction removable ÷ quality risk.
## 2. System prompt and injected context
Label every instruction:
- Keep: product or environment knowledge the model can't infer, fixes for quirks seen in this model's transcripts, and rules a mode depends on.
- Rewrite: commands and emphasis into plain descriptions. Reminders into constraints: "No TODOs, no partial implementations" works better than "remember to finish implementations." Vague quantities into ranges: "generate 20–100 tasks" gets far more ambitious behavior than "generate many tasks."
- Delete: things capable models do by default, guards against behavior you haven't seen from this model, text that repeats tool descriptions, and lines that could contradict a user request. Models trained to rank system instructions above user messages will side with the system prompt.
- Move: anything per-user or per-request (date, environment, repo state, lists of skills or subagents, user rules) into a user-role setup message after the cache boundary.
Audit other injected context the same way. As models improved, the team behind these figures dropped directory trees, pre-retrieved snippets, compressed copies of attached files, lint errors injected after every edit, forced expansion of short file reads, and caps on tool calls per turn. They kept small, high-value facts: OS, repo status, and open or recently viewed files.
Skip checklists for open-ended work. The model optimizes the listed items and deprioritizes everything else.
## 3. Tool definitions
Tool schemas ride along on every request. Most tools beyond the core set were each needed in under 20% of conversations, and moving them out of static context cut tool-description tokens 60%. Doing the same for integration tools (such as MCP servers), with names in context and full schemas in one folder per server that the agent can search with grep or jq, cut total tokens 46.9% in sessions that used them.
- Keep in static context: high-frequency tools (for a coding agent: read, search, edit, shell), tools the model tries to call even when they're absent, and tools a mode depends on.
- Offload the rest: leave a name or one-line pointer and make the full schema discoverable on demand. Group related tools so they load together, and put status (such as "needs re-authentication") where the agent will see it.
- Tighten what remains: describe behavior and arguments, and drop usage lectures.
- Pick the split by testing a few configurations and tracking tokens, cost, latency, tool-call errors, and task success.
## 4. Cache layout
Order each request so the reusable prefix is as long as possible:
`tool definitions → system instructions → [breakpoint] → setup message (skills, subagents, rules, environment) → [breakpoint] → conversation`
- Keep the prefix byte-identical across turns. Use deterministic tool order and serialization, put timestamps and IDs after the boundary, and don't rewrite earlier messages except when compacting.
- Use explicit breakpoints if the provider supports them. Otherwise rely on automatic prefix caching with the stable part first. Respect TTL and minimum-length rules.
- Switching models mid-conversation throws away the cache (caches are per model and provider) and hands the new model a history it didn't write. When a different model is needed, run it as a subagent with fresh context.
Explicit breakpoints plus moving per-request setup after them cut cold cache misses 20%.
## 5. Tool results and other context added during a run
- Large outputs (commands, integrations, logs): write them to a file and return the path, size, and a short tail. The agent can tail, grep, or read ranges for more. Truncating loses data, and inlining bloats every later request. Treat long-running terminal sessions the same way.
- High-volume formats: look for overhead repeated on every line or item. Numbering every 10th line of a file read instead of every line cut cache-read tokens 1.6% without hurting citation accuracy. Each number costs 3–5 tokens, and agents read tens of thousands of lines per session. Also check repeated absolute paths, verbose JSON keys, ANSI codes, progress bars, and repeated headers.
- Good retrieval saves exploration turns. Adding semantic search alongside grep raised codebase question-answering accuracy 12.5% on average and cut the iterations users needed.
- Tool errors waste tokens and leave confusing debris in context. Classify expected errors (invalid arguments, unexpected environment, provider error, timeout, user abort), treat unknown errors as harness bugs, and track rates per tool and per model. One focused effort along these lines cut unexpected tool errors 10×.
## 6. Long runs: compaction, subagents, and model mix
- Compaction: keep the summarization prompt short and the summary compact, carry forward plan state and remaining tasks, and save the full history to a file the agent can search for details the summary dropped. A model trained to self-summarize from a one-line prompt wrote ~1k-token summaries with half the compaction error of a multi-thousand-token prompt that produced 5k+ token summaries. Untrained models may need more guidance, so test how short you can go. A more expensive summarization model made a negligible difference.
- Scratchpads and running notes: rewrite them instead of appending. For repeated work in one environment, a small agent-maintained notes file with a line budget, loaded at start, is a promising way to shorten later runs.
- Subagents: fresh context keeps the parent lean, but isolation adds coordination cost (duplicate or stale work). If the model already delegates on its own, remove prompting that pushes it to. Have subagents return short handoffs: what was done, findings, concerns, and deviations. A subagent should use a different model only when the user or harness says so.
- Model mix: in large multi-agent runs, workers used at least 69% of tokens, and over 90% in most runs. A frontier planner with cheap workers matched a frontier model doing everything at about one-eighth the cost. Planner choice still changes worker spend. One planner that cost less on its own saw its workers use several times more tokens, and the run cost more overall. Measure the whole tree.
- Routing and reasoning effort: send simple turns to a cheaper model or lower effort, and upgrade only when a stronger model is clearly better. A router built this way matched or beat single frontier models on user satisfaction at 41–68% lower cost.
- Reasoning continuity: if the API returns reasoning items (including encrypted ones), pass them back on later turns and alert when they go missing. Dropping them cost one reasoning model 30% on a coding benchmark, and it burned tokens reconstructing its plan.
## 7. Fit the harness to each model
Adapt to what each model was trained on instead of forcing one shape on all of them. If you've tuned the harness for a similar model, start from that version.
- Edit format: use the one the model was trained on (for example, patch-style or search-and-replace). An unfamiliar format costs extra reasoning tokens and causes more mistakes.
- Shell or tools: shell-first models fall back to `cat` or inline scripts. Name tools after their shell equivalents (such as `rg`), and if needed add: "If a tool exists for an action, prefer to use the tool instead of shell commands (e.g. read_file over `cat`)."
- Literalness: some model families follow instructions literally and others tolerate imprecision. Some spiral on emphasized wording. Strip caps and emphasis for literal models.
- Triggers: some models ignore a tool until told when to use it. A literal trigger works: "After substantive edits, use the to check recently edited files for linter errors. If you've introduced any, fix them if you can easily figure out how."
- Progress updates: if a model reports progress through reasoning summaries, keep them to 1–2 sentences that note new findings or a change of tactic, and remove instructions about messaging mid-turn.
- Quirks worth a targeted line: hedging or refusing as context fills ("context anxiety"), declaring completion early, stopping to ask permission, and calling tools that don't exist.
Tie each added instruction to the transcript behavior it fixes. Re-audit when models change, since guidance one version needed can be dead weight for the next.
## 8. Validate
- Offline: run a fixed set of realistic tasks before and after, ideally drawn from real usage and phrased the way users actually write (short and ambiguous). Compare task success, tokens, cost per task, turns, and tool errors. Don't ship a change that lowers success.
- Online, if you have users: A/B test each change or small bundle. The primary metric is cost per completed task. Guardrails are task success signals, tool-call errors, latency, turns per task, and cache hit rate. For a coding agent, a good success signal is how much agent-written code survives over time. In general, check whether the user's next message moves on or reports a problem.
- Ship only when cost drops and no guardrail regresses beyond noise. Record null results.
## What to change directly and what to propose
- Change directly, each in its own revertible commit: token and cache telemetry, deterministic serialization and tool order, moving volatile content out of the cached prefix, explicit cache breakpoints, writing large outputs to files instead of truncating, passing back reasoning items that are being dropped, and fixes for recurring tool errors.
- Change behind a flag so it can be tested: system prompt edits, tool offloading, output format changes, compaction changes, and subagent prompting.
- Propose only: changes to which models run, routing, reasoning-effort defaults, or how work is split across agents.
## Traps
- Asking the model to use fewer tokens or do less.
- Truncating tool output.
- Dropping reasoning items to save input tokens.
- Volatile content in the cached prefix, or tool order that changes between requests.
- Offloading a tool the model needs on the first turn or tries to call when it's missing.
- Emphasis-heavy prompts (MUST, NEVER, IMPORTANT, all caps), especially with literal models.
- Forcing a terser output format than the model was trained on. Fewer output tokens can mean less thinking and worse results.
- Optimizing raw token counts instead of cost, per request instead of per task, or evals instead of real usage.
- Switching models mid-conversation to save money.
- Adding coordination layers that become bottlenecks.
## Report back with
1. The harness map and baseline: cost by source × billing type, with the biggest sources called out.
2. A ranked list of changes: layer, what changes, estimated savings and how you estimated them, quality risk, how to validate, and how to roll back.
3. The changes you made, including a system prompt diff with a keep, rewrite, delete, or move reason for each line.
4. A test plan for the flagged changes.
5. Gaps: anything you couldn't find or measure.
显示更多