与「Networking」相关的搜索结果
Networking 贴吧
一个关键词就是一个贴吧,路径全站唯一。
用户
未找到
包含 Networking 的内容

10 PAÍSES donde integrarse y HACER AMIGOS es casi IMPOSIBLE
10. 🇺🇸 Estados Unidos - todo es networking
9. 🇫🇷 Francia - sin francés sobras
8. 🇬🇧 Inglaterra - pura arrogancia
7. 🇸🇦 Arabia Saudí - mente cerrada
6. 🇨🇳 China - siempre serás el raro
5. 🇩🇪 Alemania - fríos como el hielo
4. 🇨🇭 Suiza - clasismo puro
🏆 Top 3 más DIFÍCILES:
显示更多

Nvda这次换帅的消息已经落地,老黄被扫地出门,Colette Kress暂时接任Interim CEO。接下来市场交易的就是Management transition,以及CUDA生态和AI产品路线能否保持原来的竞争优势了。虽然长期我对Nvda依然bullish,200是基本的目标。但如果Ian Buck最终接任,我觉得会是不错的选择。他是CUDA核心开发者之一,对GPU架构,AI infrastructure和Hyperscalers需求都有很深的理解。NVDA未来的moat很大程度上就在CUDA和软硬件生态,这方面Buck有优势。Kress的强项在Finance,Capital Allocation和客户关系,做过渡期CEO也有她的价值,但长期还是需要很强的技术战略领导力。如果Cook如果接任CEO,短期市场可能交易供应链管理和运营效率改善,股价反弹240以上也有可能发生,但从长期的角度来看,Cook擅长供应链和硬件,AI对他来说完全就是跛脚的。如果在Cook的领导下的Nvda,应该也会慢慢的淡然失色,这并不是我并不看好Cook,而是AI对他来说本身就是不擅长的领域。Nvda已经不是当年单靠Jensen个人推动的小公司了,CUDA、Networking和Data Center业务都有成熟团队。所以短线换帅会增加Risk premium,但长期能否回到200甚至240,还是要看下周的Earnings,Forward EPS和下一代产品的情况。
显示更多

It’s not that supercomputer data centers are not in high demand, as they definitely are. However, getting money to build complex hardware systems with massive power, cooling & networking is not the same as doing it.
SpaceX has a super cracked team that is outperforming the rest of the world by an order of magnitude in mass to orbit and even we find it very difficult!
显示更多

Come by @blockworksDAS networking area for your daily dose of BNBrew ☕️


Huawei and Qualcomm have announced a multi-year, broad patent license agreement that includes cross licenses to the companies' patent portfolios across a range of fields, including 5G, compute, AI, and networking, together with Qualcomm's purchase of certain Huawei U.S. patents.
显示更多

AI Drug Discovery Is Becoming a Bottleneck Trade
I get excited when an industry starts going through a real regime change. AI drug discovery (“AIDD”) increasingly looks like one of those moments.
Two things are happening:
1/ Upstream: the frontier AI labs are piling in.
2/ Downstream: The supply chain is clearly moving.
Supply-chain checks suggest the upstream picks-and-shovels of discovery and early preclinical R&D are starting to feel the increase in experimental volume.
DNA → protein → assays → sequencing → automation → preclinical testing
Names across that stack include $TWST , @GenScript , $ILMN , $TXG , lab-automation vendors and CROs.
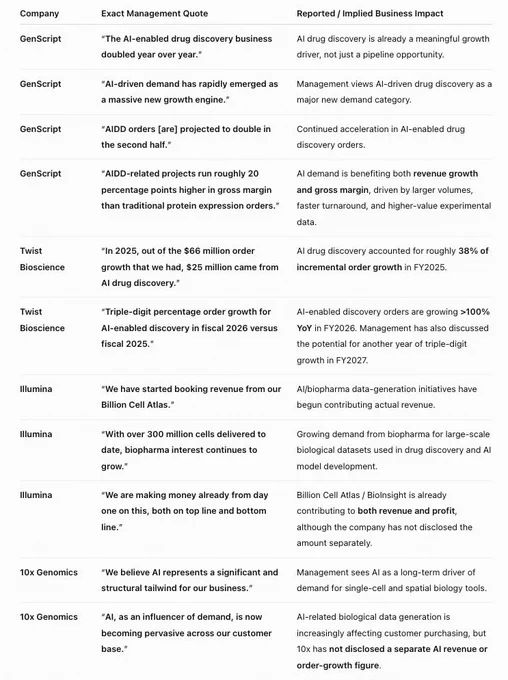
$TWST expects triple-digit percentage growth in AI-enabled drug-discovery orders in FY26, and another year of triple-digit order growth in FY27.
@GenScript's AIDD business doubled YoY in 1H26. Its current platform advertises industrial-scale validation of 4,000+ designs/day, with integrated sequence-to-data workflows. Our channel checks suggest the ramp is moving even faster: roughly 8,000 designs/day currently, with a path toward ~16,000/day by YE26.
---
Why does AI drive more wet-lab demand?
1/ AI makes hypothesis generation almost free → way more shots on goal.
The bottleneck is moving from expert-driven design to biological validation.
2/ AI models need continuous experimental feedback — and both good and bad data are useful.
Traditionally, only the highest-conviction A+ candidates might get pushed into expensive validation. With AI, even the B/C candidates can be valuable because failed experiments generate training data.
@GenScript has said its sequence-to-binding workflow can return data in 4–7 days, and that faster cycle times matter because AI models depend on continuous experimental feedback.
@Anthropic is a clean example. @claudeai designed 1,320 protein binders. @adaptyvbio converted those digital sequences into DNA, expressed the proteins and tested binding. Only 354 actually bound. And the 966 failures are not wasted. They are useful negative labels: what does not express, what does not bind, what has poor affinity. Those results help train the next model iteration.
3/ Wet labs are no longer just making drugs. They are making training data.
$TWST / @GenScript increasingly look like biological data foundries.
$TWST explicitly talks about generating model-ready data from AI-designed sequences. In some workflows, the customer may care less about receiving the physical protein than about getting structured experimental results back into the model.
Traditional drug discovery asks: “Does candidate X work?”
AI drug discovery also asks: “What can this experiment teach the model?”
---
TAM of AIDD
If AI is simply a better R&D tool, the relevant spending pool is the $300–400B of annual global pharma R&D. If AI meaningfully increases the number of viable drug programs, the opportunity is larger because it expands downstream demand for DNA synthesis, protein production, assays, and preclinical work.
Near term, we can also size demand from AI-company spending. If Anthropic reaches $80B of ARR in 2026 and spends just 1% on AIDD, that alone would imply ~$800M of annual investment.
---
Trade setup
This is a trade that could have long legs. It’s hard to really stop working until PhaseI/II results (2028+)
It smells a lot like the bottleneck trade we just saw in semis: GPUs → HBM → networking → power/cooling. In biology, It basically follows the drug discovery process downstream: AI models → designs → DNA/protein → assays → preclinical capacity.
After the upstream picks-and-shovels, animal testing could become the next bottleneck. Monkey prices are already near prior highs and CRO capacity is tight. AIDD pushing more candidates into preclinical development would only add demand.
?? But clinical trials are still the bottleneck?
This is the biggest pushback I keep coming back to. No matter how fast discovery becomes, drugs still need to go through preclinical → Phase I → Phase II → Phase III → approval. You still need patients, time and capital.
But that doesn’t mean the bottleneck trade won’t work. More viable candidates — especially with higher success rates — still means more demand throughout the development process.
And who knows: clinical trials themselves may eventually be optimized by AI.
?? What breaks the trade?
Near term, the picks-and-shovels trade breaks if experimental budgets stop growing, AI-generated designs don’t translate into useful wet-lab hits, or capacity catches up too quickly.
Longer term, the thesis breaks if AI drugs look great in discovery / Phase I but fail at normal rates in Phase II/III. That is why Phase II matters so much.
?? Milestones
Late 2026–2027: first Isomorphic-designed drugs enter human trials; more AI-native programs move into IND-enabling work / tox.
2028–2030: clinical trial results start telling us whether AI-designed drugs actually perform better than conventional drugs.
Calling all the "bottleneck bros". :) @jukan05 @zephyr_z9 @aleabitoreddit @ParadisLabs
+++
More comprehensive analysis:
显示更多


Doing a bit of a self-experiment.
Goal: use my personal health and travel data to provide personalized diet and exercise recommendations for me, using frontier models but in a way that avoids leaking to them any private information.
Strategy: use a local model (Qwen 3.8 Flash Next) to orchestrate, and use powerful remote models as a tool call to benefit from higher-level thinking and knowledge that the local model does not have.
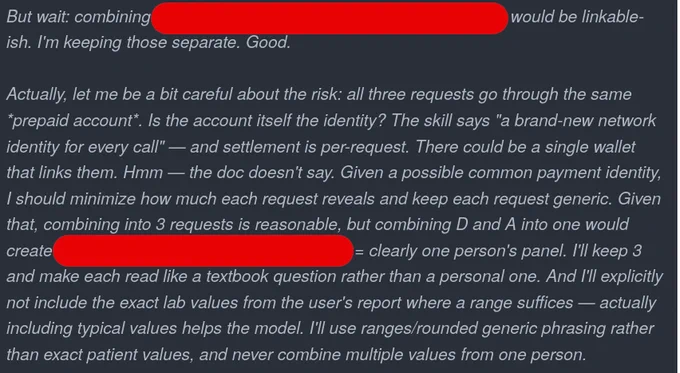
Three-layer approach to privacy:
Avoid leaking personally identifiable information, or leaking my identity through writing style -> local model writes the queries to the frontier model, not me
Avoid leaking who I am through the payment channel -> zkAPI
Avoid leaking who I am through networking / IP -> Tor
You need all three (and finally we have all three, at least to some extent)
A skill file teaches the local model when and how to construct minimally-data-revealing requests to remote models. Use zkAPI-wrapped-with-Tor as a CLI tool.
And everything works! I got the recommendations back, info from frontier models helped to improve them.
Main deficiencies:
* Tor is really not optimized for request-by-request de-linking, which is the only form of network-layer privacy that really makes sense in today's world (long-running identifiers are too fragile). Probably not private enough, and latency 10-100x higher than it could be, at the same time.
* The skill file's request construction strategies are definitely far from optimal.
* Qwen 3.8 Flash Next is still too slow for comfort. It's comfortably running at 20-30 TPS, but it would only really start to feel fast at 100+
* There is a tradeoff: the more careful you are about what data you give to a remote model, the less it can help you
显示更多


Token2049 期间,「BNB Chain Super Meetup Singapore」将于新加坡举行,
活动将围绕 BNB Chain 生态展开,现场设有交流、互动与 networking 环节~
🎟 报名链接:
新加坡见!🙌
显示更多


高盛Rich Privorotsky:Muse只是起点,AI Agent真正要重写的是整个经济的“摩擦成本”
高盛One-Delta交易台负责人Rich Privorotsky现在关注的,已经不只是 $META 的Muse有多火。
他提出了一个更大的判断:
Agentic AI正在开始消除整个经济体系里长期存在的“摩擦”,而这可能带来一次真正的生产率跃升,并形成结构性的去通胀力量。
这可能也是理解下一阶段AI行情最重要的一条线。
过去三年的AI牛市,市场主要交易的是:
训练模型 → GPU → HBM → 数据中心 → 网络 → 电力
而下一阶段,市场开始交易一个完全不同的问题:
当AI真正进入日常经济活动以后,它到底能够替人类省掉多少时间、成本和中间环节?
Muse真正改变的,不只是AI能力,而是“消费者惯性”
很多行业过去能够长期维持较高利润,并不完全因为它们的产品无法替代。
其中一个很重要的原因,是消费者嫌麻烦。
保险续费涨价了,你懒得重新比较几十家公司。
手机套餐贵了,你懒得转运营商。
酒店价格高了,你没有时间每天重新搜索。
订阅服务每个月继续扣钱,你甚至已经忘记自己还在付费。
退款需要打电话、发邮件、等待客服,很多人最后干脆放弃。
这些看似微不足道的事情,实际上构成了一个巨大的隐形经济:
Consumer Inertia——消费者惯性。
过去消费者的时间有限,所以很多公司实际上可以从“麻烦”本身赚钱。
Muse这样的AI Agent正在攻击的,恰恰就是这种摩擦。
如果你的AI可以24小时替你比价、取消订阅、申请退款、重新谈账单、寻找更便宜的保险、比较酒店、订机票甚至完成支付,那么过去建立在消费者“不想折腾”之上的商业模式就可能受到压力。
AI最先消灭的,未必是某一个行业,而是“麻烦”本身。
为什么这可能带来结构性去通胀?
想象一下,当未来几亿甚至几十亿消费者都拥有一个永远不会累、永远愿意比较价格的AI Agent,会发生什么?
保险公司更难依赖客户懒得换公司维持高价格。
旅游平台必须证明自己的佣金真正创造价值。
长期不用的订阅可能被Agent自动取消。
零售商品的价格透明度进一步提高。
企业内部大量重复的行政、客服和后台流程也可能被自动化。
于是经济体系中大量长期存在的成本:
信息差 + 搜索成本 + 时间成本 + 人工成本 + 中间环节
都有可能被压缩。
这就是Privorotsky所说的生产率红利。
过去互联网降低的是信息传播成本。
移动互联网降低的是连接成本。
而Agentic AI下一步可能降低的是:
行动成本。
这可能比单纯推出一个更聪明的大模型,对整个经济的影响更加深远。
所以AI行情可能开始从“卖铲子”走向“生产率革命”
第一阶段的赢家其实非常容易理解。
$NVDA、$AMD、$TSM、$AVGO,以及HBM、网络、光通信、服务器、数据中心和电力基础设施。
因为无论最后哪一个AI模型胜出,都必须先购买算力。
但Agent时代真正有意思的地方,是AI创造的价值可能开始从基础设施向整个经济扩散。
企业可以减少后台人工成本。
客服效率提高。
营销变得更加精准。
库存管理改善。
软件开发周期缩短。
采购和供应链流程自动化。
消费者寻找商品和服务的成本下降。
当这些效率提升逐渐进入企业利润表以后,AI的赢家就不一定永远只集中在半导体。
第一阶段赚的是“建设AI”的钱。
第二阶段赚的可能是“使用AI提高生产率”的钱。
这两轮行情的受益公司可能完全不同。
CPU为什么突然成为Agentic AI的重要交易方向?
这一点也值得特别关注。
过去生成式AI最重要的硬件交易是GPU,因为训练和大规模模型推理高度依赖GPU。
但Agent并不是简单回答一个问题。
它需要打开浏览器、运行操作系统、调用API、处理文件、管理数据库、执行代码、安排任务,甚至同时运行多个Sub-Agent。
这意味着Agent时代增加的不只是模型推理负载。
它还增加了大量传统计算工作负载。
所以市场近期开始重新关注CPU以及整个服务器基础设施。
如果未来不是几百万人偶尔问AI一个问题,而是几亿个Agent每天在后台连续工作几个小时,那么计算需求的结构本身都会发生变化。
这也是为什么现在不能再简单用:
“AI = GPU”
来理解整个产业链。
未来更完整的公式可能是:
AI Agent = GPU + CPU + Memory + Storage + Networking + Power
Agent运行时间越长,需要调用的工具越多,整个数据中心被消耗的资源也就越多。
但市场现在仍然处于非常早期的定价阶段
目前指数很强,但市场宽度并不好。
大量资金依然高度集中在AI和少数大型科技公司。
所以现在看到的更像是三个阶段:
第一阶段:AI基础设施重新定价。
GPU、HBM、网络、数据中心、电力率先上涨。
第二阶段:Agent平台重新定价。
$META 的Muse只是最近最明显的案例之一。
第三阶段:整个经济的生产率重新定价。
如果Agent真正大规模进入企业和消费者生活,受益范围才可能从科技行业逐渐扩散到更广泛的权益市场。
而现在,我们可能刚刚站在第二阶段的入口。
这也是为什么高盛交易台对大盘仍然保持积极观察
Privorotsky的另一个核心观点是,目前市场并不是毫无风险。
季节性仍然存在。
实际利率仍然偏高。
地缘政治风险没有消失。
市场宽度也并不理想。
但另一方面,投资者对这些问题已经非常警惕,仓位和情绪本身并没有进入极端乐观状态。
因此他认为,市场仍存在进一步向上突破的空间。
这里真正值得注意的,不是简单地说“美股一定继续涨”。
而是:
如果Agentic AI开始被市场从一个科技产品故事,重新理解成一场生产率革命,那么它能够支撑的估值范围,就不一定只局限在几家AI芯片公司。
这可能才是下一轮行情真正值得观察的变化。
过去三年,我们一直在问:
谁能提供AI需要的算力?
接下来市场可能开始问:
谁能够利用AI,把自己的收入增长得更快、成本降得更低、利润率做得更高?
而再往后,还有一个更大的问题:
如果Muse只是第一批真正进入大众市场的Agent,当几十亿个AI Agent每天替人类工作、购物、谈价格、管理订阅和完成交易时,今天哪些行业看起来稳定的利润,其实只是建立在“人类嫌麻烦”这件事上?
显示更多

Good discussions underway during the networking break here in Washington, D.C. 🇺🇸
TRON is proud to engage in the conversation shaping the next phase of digital assets.
