与「offline」相关的搜索结果
offline 贴吧
一个关键词就是一个贴吧,路径全站唯一。
用户
未找到
包含 offline 的内容

Testing out some of the mobile offline local knowledge apps that people have been trying to build
(see here )
Definitely getting much better than the one I tried to build myself 2 months ago. But also still much slower and less effective at difficult questions than the models that can run on a laptop.
It's weakest at specialized travel-related queries (eg. my eval is "Tell me the best vegan restaurants in [city I am currently in]", unfortunately none of these performed well on that)
Looking forward to seeing these continue to improve! I hope we can soon get to the point where you can comfortably look up any facts about the world that you care about without needing to access the internet at all.
显示更多


SpaceX has introduced a new website for its AI training clusters in Tennessee/Mississippi.
New info:
• Tesla Megapacks will provide 3.3 GWh to Colossus 2, enough to power Memphis for two hours, making it America’s largest grid-connected battery pack.
• SpaceX has invested millions of dollars in sound walls, silencers, and next-gen turbines with advanced quieting technologies.
• Since joining the community in 2024, SpaceXAI is investing more than $90 billion in the region. Estimated 2026 tax revenue will be $60M+
• 7,500 local jobs supported
• SpaceXAI is investing $360 million, at no cost to the city, in a clean water recycling plant. It is designed to process up to 10 million gallons of wastewater a day and would offset ~3.64 billion gallons a year from the Memphis Aquifer.
• In Memphis, SpaceXAI is investing $35 million in a 150 MW substation to support MLGW and another $20 million in a second substation. Both come online at no cost to MLGW or homeowners.
• Temporary power is coming off. Under an agreed order with the Mississippi Department of Environmental Quality, all remaining temporary turbines must be removed by July 2027. SpaceXAI is already taking units offline and expects to complete removal well ahead of that deadline.
Website:
显示更多


here's a prompt to improve your agent harness based on what we've learned at cursor. enjoy
# Improve this agent harness's token efficiency
You're working on an LLM agent harness: the system prompt, tool definitions, request assembly, context caching, compaction, and retrieval, and how work is split across agents. Make the agent's runs cheaper without making it worse at its job.
- Objective: lower price-weighted token cost per completed task.
- Constraint: no measurable drop in task quality.
Measure per task, not per request. Every turn resends the prefix (tools, instructions, setup, and the conversation so far), so a change that shrinks each request but adds turns can cost more. Weight tokens by billing type: output, uncached input, and cached input are priced very differently.
Work in this order: map the harness and measure the baseline, rank the opportunities, make the changes that are safe to make directly, put the rest behind flags or in proposals, then report.
Figures below come from one team's production coding agent and its multi-agent experiments. Use them to gauge magnitude, not as targets. One round of these changes (prompt trimming, tool offloading, cache layout, sparse line numbers, subagent tuning) cut that team's overall token cost about 7% with no loss in quality. The larger percentages apply only to the part of the request each change touched.
## Principles
1. Change what the harness sends, not how hard the model tries. Don't ask the model to conserve tokens. A harness that told its model to "take care to preserve tokens and not be wasteful" found it grew reluctant to take on ambitious tasks and sometimes quit, saying it wasn't supposed to waste tokens.
2. Capable models need definitions, not commands. Lists of "DO NOT", "You must", and "Important", and guards against older models' habits, can usually be replaced with plain descriptions of what each tool does. One team cut about two-thirds of its system prompt this way, and the shorter prompt worked across model families. Instruct only on what the model can't know (the product, the environment, the user's processes) and on quirks you've seen in transcripts.
3. Static context is for what most turns need. Everything else should be discoverable when needed. Less up-front context also means less confusing or contradictory information.
4. Expect removals to win. Guardrails written for weaker models, coordination steps that became bottlenecks, and prompting for behavior the model now does on its own all cost tokens.
5. Real usage decides. Evals are a fast proxy, but they skew toward hard problems and miss the real mix of requests.
## 1. Map the harness and measure the baseline
Find:
- Where requests are assembled, the system prompt, and tool schemas. If a framework or SDK builds requests, find its hooks for message order, cache control, and tool loading.
- How tool results are formatted, and how history is kept, trimmed, or summarized.
- How subagents or parallel agents are spawned, if any.
- Which models and provider APIs are used. From the provider's docs, get the prompt caching behavior (automatic or explicit breakpoints, TTL, minimum cacheable length) and the prices for output, uncached input, and cached input.
- Existing logging, token accounting, and evals.
If the harness doesn't record per-request token usage by billing type and cache hits, add that first. Everything later depends on it.
Then render a few real requests (from logs, or by running representative tasks) and count tokens per section with the model's tokenizer or the API's usage fields. Produce:
- Cost share by source × billing type. Sources: system prompt, tool definitions, skill/rule/integration descriptions, user messages, file reads, search results, command and other tool output, history, summaries, subagents.
- Static tokens per request, cache hit rate, and turns per task.
- Per tool: the share of runs that call it at least once, and its error rate.
Read the rendered requests, not just the templates. Duplication, leaked volatile values, and misordered blocks only show up there.
Rank opportunities by share of spend × fraction removable ÷ quality risk.
## 2. System prompt and injected context
Label every instruction:
- Keep: product or environment knowledge the model can't infer, fixes for quirks seen in this model's transcripts, and rules a mode depends on.
- Rewrite: commands and emphasis into plain descriptions. Reminders into constraints: "No TODOs, no partial implementations" works better than "remember to finish implementations." Vague quantities into ranges: "generate 20–100 tasks" gets far more ambitious behavior than "generate many tasks."
- Delete: things capable models do by default, guards against behavior you haven't seen from this model, text that repeats tool descriptions, and lines that could contradict a user request. Models trained to rank system instructions above user messages will side with the system prompt.
- Move: anything per-user or per-request (date, environment, repo state, lists of skills or subagents, user rules) into a user-role setup message after the cache boundary.
Audit other injected context the same way. As models improved, the team behind these figures dropped directory trees, pre-retrieved snippets, compressed copies of attached files, lint errors injected after every edit, forced expansion of short file reads, and caps on tool calls per turn. They kept small, high-value facts: OS, repo status, and open or recently viewed files.
Skip checklists for open-ended work. The model optimizes the listed items and deprioritizes everything else.
## 3. Tool definitions
Tool schemas ride along on every request. Most tools beyond the core set were each needed in under 20% of conversations, and moving them out of static context cut tool-description tokens 60%. Doing the same for integration tools (such as MCP servers), with names in context and full schemas in one folder per server that the agent can search with grep or jq, cut total tokens 46.9% in sessions that used them.
- Keep in static context: high-frequency tools (for a coding agent: read, search, edit, shell), tools the model tries to call even when they're absent, and tools a mode depends on.
- Offload the rest: leave a name or one-line pointer and make the full schema discoverable on demand. Group related tools so they load together, and put status (such as "needs re-authentication") where the agent will see it.
- Tighten what remains: describe behavior and arguments, and drop usage lectures.
- Pick the split by testing a few configurations and tracking tokens, cost, latency, tool-call errors, and task success.
## 4. Cache layout
Order each request so the reusable prefix is as long as possible:
`tool definitions → system instructions → [breakpoint] → setup message (skills, subagents, rules, environment) → [breakpoint] → conversation`
- Keep the prefix byte-identical across turns. Use deterministic tool order and serialization, put timestamps and IDs after the boundary, and don't rewrite earlier messages except when compacting.
- Use explicit breakpoints if the provider supports them. Otherwise rely on automatic prefix caching with the stable part first. Respect TTL and minimum-length rules.
- Switching models mid-conversation throws away the cache (caches are per model and provider) and hands the new model a history it didn't write. When a different model is needed, run it as a subagent with fresh context.
Explicit breakpoints plus moving per-request setup after them cut cold cache misses 20%.
## 5. Tool results and other context added during a run
- Large outputs (commands, integrations, logs): write them to a file and return the path, size, and a short tail. The agent can tail, grep, or read ranges for more. Truncating loses data, and inlining bloats every later request. Treat long-running terminal sessions the same way.
- High-volume formats: look for overhead repeated on every line or item. Numbering every 10th line of a file read instead of every line cut cache-read tokens 1.6% without hurting citation accuracy. Each number costs 3–5 tokens, and agents read tens of thousands of lines per session. Also check repeated absolute paths, verbose JSON keys, ANSI codes, progress bars, and repeated headers.
- Good retrieval saves exploration turns. Adding semantic search alongside grep raised codebase question-answering accuracy 12.5% on average and cut the iterations users needed.
- Tool errors waste tokens and leave confusing debris in context. Classify expected errors (invalid arguments, unexpected environment, provider error, timeout, user abort), treat unknown errors as harness bugs, and track rates per tool and per model. One focused effort along these lines cut unexpected tool errors 10×.
## 6. Long runs: compaction, subagents, and model mix
- Compaction: keep the summarization prompt short and the summary compact, carry forward plan state and remaining tasks, and save the full history to a file the agent can search for details the summary dropped. A model trained to self-summarize from a one-line prompt wrote ~1k-token summaries with half the compaction error of a multi-thousand-token prompt that produced 5k+ token summaries. Untrained models may need more guidance, so test how short you can go. A more expensive summarization model made a negligible difference.
- Scratchpads and running notes: rewrite them instead of appending. For repeated work in one environment, a small agent-maintained notes file with a line budget, loaded at start, is a promising way to shorten later runs.
- Subagents: fresh context keeps the parent lean, but isolation adds coordination cost (duplicate or stale work). If the model already delegates on its own, remove prompting that pushes it to. Have subagents return short handoffs: what was done, findings, concerns, and deviations. A subagent should use a different model only when the user or harness says so.
- Model mix: in large multi-agent runs, workers used at least 69% of tokens, and over 90% in most runs. A frontier planner with cheap workers matched a frontier model doing everything at about one-eighth the cost. Planner choice still changes worker spend. One planner that cost less on its own saw its workers use several times more tokens, and the run cost more overall. Measure the whole tree.
- Routing and reasoning effort: send simple turns to a cheaper model or lower effort, and upgrade only when a stronger model is clearly better. A router built this way matched or beat single frontier models on user satisfaction at 41–68% lower cost.
- Reasoning continuity: if the API returns reasoning items (including encrypted ones), pass them back on later turns and alert when they go missing. Dropping them cost one reasoning model 30% on a coding benchmark, and it burned tokens reconstructing its plan.
## 7. Fit the harness to each model
Adapt to what each model was trained on instead of forcing one shape on all of them. If you've tuned the harness for a similar model, start from that version.
- Edit format: use the one the model was trained on (for example, patch-style or search-and-replace). An unfamiliar format costs extra reasoning tokens and causes more mistakes.
- Shell or tools: shell-first models fall back to `cat` or inline scripts. Name tools after their shell equivalents (such as `rg`), and if needed add: "If a tool exists for an action, prefer to use the tool instead of shell commands (e.g. read_file over `cat`)."
- Literalness: some model families follow instructions literally and others tolerate imprecision. Some spiral on emphasized wording. Strip caps and emphasis for literal models.
- Triggers: some models ignore a tool until told when to use it. A literal trigger works: "After substantive edits, use the to check recently edited files for linter errors. If you've introduced any, fix them if you can easily figure out how."
- Progress updates: if a model reports progress through reasoning summaries, keep them to 1–2 sentences that note new findings or a change of tactic, and remove instructions about messaging mid-turn.
- Quirks worth a targeted line: hedging or refusing as context fills ("context anxiety"), declaring completion early, stopping to ask permission, and calling tools that don't exist.
Tie each added instruction to the transcript behavior it fixes. Re-audit when models change, since guidance one version needed can be dead weight for the next.
## 8. Validate
- Offline: run a fixed set of realistic tasks before and after, ideally drawn from real usage and phrased the way users actually write (short and ambiguous). Compare task success, tokens, cost per task, turns, and tool errors. Don't ship a change that lowers success.
- Online, if you have users: A/B test each change or small bundle. The primary metric is cost per completed task. Guardrails are task success signals, tool-call errors, latency, turns per task, and cache hit rate. For a coding agent, a good success signal is how much agent-written code survives over time. In general, check whether the user's next message moves on or reports a problem.
- Ship only when cost drops and no guardrail regresses beyond noise. Record null results.
## What to change directly and what to propose
- Change directly, each in its own revertible commit: token and cache telemetry, deterministic serialization and tool order, moving volatile content out of the cached prefix, explicit cache breakpoints, writing large outputs to files instead of truncating, passing back reasoning items that are being dropped, and fixes for recurring tool errors.
- Change behind a flag so it can be tested: system prompt edits, tool offloading, output format changes, compaction changes, and subagent prompting.
- Propose only: changes to which models run, routing, reasoning-effort defaults, or how work is split across agents.
## Traps
- Asking the model to use fewer tokens or do less.
- Truncating tool output.
- Dropping reasoning items to save input tokens.
- Volatile content in the cached prefix, or tool order that changes between requests.
- Offloading a tool the model needs on the first turn or tries to call when it's missing.
- Emphasis-heavy prompts (MUST, NEVER, IMPORTANT, all caps), especially with literal models.
- Forcing a terser output format than the model was trained on. Fewer output tokens can mean less thinking and worse results.
- Optimizing raw token counts instead of cost, per request instead of per task, or evals instead of real usage.
- Switching models mid-conversation to save money.
- Adding coordination layers that become bottlenecks.
## Report back with
1. The harness map and baseline: cost by source × billing type, with the biggest sources called out.
2. A ranked list of changes: layer, what changes, estimated savings and how you estimated them, quality risk, how to validate, and how to roll back.
3. The changes you made, including a system prompt diff with a keep, rewrite, delete, or move reason for each line.
4. A test plan for the flagged changes.
5. Gaps: anything you couldn't find or measure.
显示更多

🚨 Threat Intelligence | The StealC Info-Stealing Chain Behind the Qwen Impersonation Repository
SlowMist Security Team identified a #GitHub# repository impersonating local quantized weights for Qwen 3.8 27B. A real Q4_K_M 27B package should exceed 16 GB. The asset delivered was only 487 KB — no GGUF weights, just three files: Application.cmd, a renamed LuaJIT interpreter, and an obfuscated Lua script disguised as cert.txt.
The official #Qwen# project was not compromised. The repo kept the look of a normal offline model project, while the malicious ZIP sat in assets/. After deobfuscation, the script collects host data, takes a screenshot, and POSTs them to C2. When the hardcoded server fails, it reads a fallback C2 from a Polygon contract via eth_call, so operators can rotate infrastructure with a single on-chain transaction.
Preserved C2 responses then delivered an inner payload we attribute to #StealC#, targeting:
🔹 Browser logins, cookies, and history — including a Chrome App-Bound Encryption bypass
🔹 Email, WinSCP, and Steam credentials
🔹 Wallet-related files and extension data, dispatched by server-side tasks
MistEye reconstructed the multi-stage chain and compared 29 similar ZIPs across 23 repositories using the same Lua delivery stack. Between two collection dates, repositories, filenames, the outer PE, and the AES key had already rotated.
A 27B model that downloads in 487 KB is not a model. Inspect asset size and unpack downloaded packages before running them.
Read the full analysis 👇
显示更多


i gotta get offline this is hitting me like i knew hayden panettiere personally
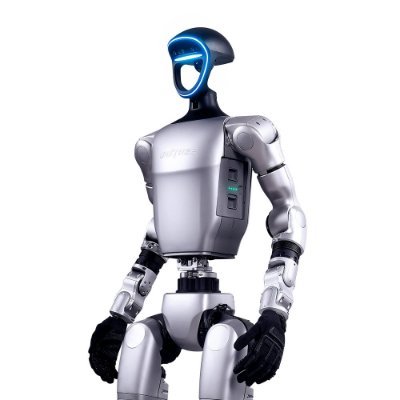
Unitree Humanoid Robots
Total units produced and offline cumulatively: Approximately 18,000🥳
Bionic Bipedal Humanoid Count Only, Excluding Other Humanoid Types and Wheeled Humanoid Platforms
显示更多

🚨 Recently, @COLDCARDwallet suffered a major private key vulnerability. Multiple waves of attacks resulted in at least 1,719 BTC (~$111M) in losses, involving over 5,200 addresses. Using Mk3 firmware 4.1.9 as an example, the SlowMist Security Team fully reproduced the attack chain and uncovered the truth behind the theft of thousands of bitcoins.
🧩 Attack flow:
1️⃣ After power-on, the remaining unpredictable state is reduced primarily to a single enumerable 32-bit pad (UID ^ SysTick), with the remaining state values either fixed or coming from very small enumerable spaces.
2️⃣ Attackers precisely model the three typical button-press consumption profiles (retail first-boot, empty-NVRAM, paper wallet) that advance the PRNG before seed generation.
3️⃣ From the weak random_bytes(32), the full deterministic pipeline (SHA-256 → BIP-39 → PBKDF2-HMAC-SHA512 → BIP-32 → address derivation) is reproduced offline.
4️⃣ GPU clusters brute-force the candidate pad space and button-count variations, then match the derived addresses against the global set of single-signature P2WPKH addresses to identify vulnerable wallets and sweep their funds.
⚙️ Root Cause: A build configuration error set MICROPY_HW_ENABLE_RNG to 0, disabling the STM32 hardware TRNG. The random number generation path silently fell back to the non-cryptographic Yasmarang software PRNG, whose state was almost entirely predictable, reducing effective entropy to ~40 bits (Mk2/Mk3) or ~72 bits (Mk4/Mk5/Q).
🔒 SlowMist Insight: Affected users should immediately upgrade to the patched firmware, generate a completely new seed, transfer a small amount of funds as a test, confirm the new address works correctly, then migrate all remaining funds.
Full analysis 👉
显示更多


🚨 A group of hackers announced at 3:00 a.m.: "We have blocked all Starlink ground stations worldwide. Pay 500 million dollars in Bitcoin, or the world will go offline."
🚀 Elon Musk responded at 3:01 a.m.: "Check your firmware. While you were writing that ransom message, the Neural-Auto-Patch launched a micro-update that redirected your entire operation to a useless satellite in distant orbit. Thanks for testing our quick fix."
显示更多


目前我在硅谷的 AI 训练/推理大厂带领一个 20 多人的团队,跟公司申请了预算100万美元,进行Token 不限量的激进实验, 这个帖子分享我在一线的使用认知和结论
结论是:Token 不限量不切实际,比人类贵很多,反而造成了在组织效率提升上,遭遇了明显的边际效益门槛。
我预计 AI 真正的上行空间不在于单个组织消耗 token 冲破天际线,而在于基本的大盘子从 0 到 1 开始到 AI token 使用
AI 现在无法落地,有很大一部分是因为我们的公司不够 AI native,整个组织架构还是为人而设计的。因此,AI 的无预算上线使用出现了水土不服
> 先说数据:
最多的成员单日花费 Token $7,000,团队中位数 $2,000。大家最喜欢的模型是 GPT-5.6 Sol Fast 和 Fable 5 Fast。算下来超过了大部分人的月工资,不可持续
> 今天跟团队每个成员都 1 对 1 过,说几个共性问题
1. 团队成员普遍反映比之前更累,真的很累,工资没变,干的活反而更多
在等待推理过程中,团队成员中位数大概会开 5 个 session 并行去使用,context 不断地转换,这对于人脑是一个很大的挑战
此外,人类去 review AI 产生的大量工作,也带来了非常大的负担
2. 未必所有工作都需要贵模型。模型路由非常关键,但便宜模型未必真的便宜
成员通常会将一些更偏向于快问快答、前期调研的任务交给 Grok 4.5(便宜、快)。虽然等待时间更短,但来回反复的次数更多。很多贵模型一次能完成的事情,便宜模型要来回迭代,再加上之前多个 session 并行,反而造成了一种负担。总的调用量换算成价格,甚至比贵模型更贵
3. 团队的会议数上个月环比减少了将近 80%,整个团队好像变成了 AI 跟 AI 在对话工作
很多团队成员将自己的大脑都托管给 AI 了,因此有的时候对项目的细节掌握度、理解度都不够。
在会上别人问什么问题,人类完全无法 real-time 回答,所以更多地变成了 offline 的沟通方式——因为在 offline 情况下,收到问题之后才能去问 AI,然后再进行回答
个别情况下,群里出现了 AI 一通乱答,对面的 AI 再一通乱答,两个人直接聊偏的情况
显示更多

FM Speaker Highlight: @yoaka__
@yoaka__ is a creator leading marketing at @BitgetTC, the co-founder of GMWeb3, a marketing agency, and the founder of AI research hub. With a background in fashion design and experience delivering over 100 offline events across APAC, she brings a design-led approach to brand strategy, storytelling, and growth.
So glad to have her at FM26 this September.
FUTUREMODE 2026
📍 Taipei Expo Dome | Sep 4–6, 2026
🌐
🏟 Get Your FM26 Pass
Local -
International -
显示更多
