与「DNA_ItsThatGood」相关的搜索结果
DNA_ItsThatGood 贴吧
一个关键词就是一个贴吧,路径全站唯一。
用户
未找到
包含 DNA_ItsThatGood 的内容

ทุกวัน ทุก Move มันต้องดี(น่า)💙⚡️
แบมแบมเลือกแล้ว ดีน่า High Protein 15g นมถั่วเหลืองโปรตีนสูงที่แบมดื่มทุกวัน🥛😎
ใส่สุดได้ทุกวัน มาดื่มกับแบมแบมด้วยกันนะ 😋
#DNAxBamBam# #DNA_ItsThatGood#
#มันต้องดีน่า# #ดีน่า#
显示更多

✨เซอร์ไพรส์ใหญ่ เปิดตัวพรีเซนเตอร์คนใหม่ของดีน่า✨
ไม่ต้องลุ้น ไม่ต้องเดา เพราะแค่เห็นเงาก็รู้แล้วว่า หล่อมากกกกก😎
รอรับแรงกระแทกความสนุกของ "แบมแบม" กับ "ดีน่า" ครบทุกรสชาติ พร้อมกันเร็วๆ นี้💙
#DNAxBamBam# #DNA_ItsThatGood# #มันต้องดีน่า# #ดีน่า#
显示更多

黄夹克这孩子就是太老实了,这事打死也不能认啊,认了马上就打死啊!
完全可以说:没有啦~,我和黄小姐就是普通盆友啦~,再说我现在满头白发,已经“拉缸了”,我阳痿多年了,不信可以让你老婆来试一下啦……
当年克林顿,人家把经过DNA确认的带精斑的裙子都拿出来了,老克就是没认有性关系,说是打飞机用过的纸巾不见了,不知道怎么就弄裙子上了
显示更多

AlphaGenome 2 is helping uncover the cellular drivers of disease, giving scientists a powerful tool to predict how DNA variants impact specific cell types.
Every cell in our body shares the same DNA blueprint, but different cell types (like heart muscle cells vs. immune cells) read that blueprint differently. This new @GoogleDeepMind model predicts how these specialized cells interpret DNA, turning genetic code into biological insights.
Building on AlphaGenome 1 this makes it significantly easier for researchers to link genetic findings to the root causes of disease in the specific cells where they actually unfold.
显示更多


如今太多挣米的路子,还焦虑个毛…
偏偏就是大部分人瞧不上的路子,反而特别能来钱。
简单举几个例子:
1⃣️刷TikTok上的助眠号,直接录屏搬运到国内短视频平台,把字幕翻成中文。
2⃣️母婴号直接参考BabyCenter,把解决婴儿睡眠问题的视频剪成“一招治夜醒”的短视频,宝妈们关注得特别猛。
3⃣️直接去Peloton参考健身课表,把HIIT训练计划拆成“7天瘦肚子”跟练合集,顺带卖瑜伽垫和瑜伽小工具,一卖一个准。
4⃣️婚礼策划师直接去The Knot看婚礼布景创意,同样的梦幻主题,国内报价能翻好几倍。
5.她一个朋友在拼多多卖宠物骨灰盒,一个成本不高的木盒能卖到几百块,买家不仅不嫌贵,还愿意加钱刻字、做爪印。这生意冷门到你去搜关键词,销量高的就那么几家,稍微用点心就能分到流量。而一旦客户下单,后续还能提供纪念相册、宠物DNA保存服务,复购率确实不低。
6.有搬运外网文章的,用AI翻译润色,十分钟搞定一篇产品,客单价一百多,在国内某平台销量好几万。聪明点的,整理TED、油管口语素材,在私域做成进阶内容,赚复利的钱。
7.有人总说AI是机会,但就是不知道怎么变现,倒卖AI课你又说割韭菜。好,我来告诉你,你用SD、MJ画游戏元素,草坪、齿轮、栅栏……做完拿去虚幻、Unity卖。别担心没市场,北美高中生用SD专门画2D游戏背景图,一份几十块,当天销量破百,半年卖出两万份。
我一个朋友专门给宠物设计“微缩家居”,比如狗狗的迷你沙发、猫咪的小床,每套售价几百到上千元。他甚至还推出了“宠物定制家居”,完全根据宠物主人的要求手工制作,价格翻倍。
搞钱就是卖,就是当二道贩子,就是直接做离钱最近的事情。先做再说,先做出一堆垃圾来,然后再慢慢优化。
有太多人根本不动手去做,也不屑于去做一些看起来很low的事情。永远听别人说,xx太卷,xx没前途,xx太low不值钱。
赚钱的本质是连接需求和供给,二道贩子就是最好的桥梁,没有什么low不low的。
显示更多

为啥老黄被迫公开承认?
因为对手太狠了,搞了听证会传唤。
如果是普通的流言,老黄死不承认,死不道歉,等伊朗战争继续打起来,或者下个热点起来,这事就过去了。
男女之事,除非对手手里有dna样本,有床照,有FBI的录音,否则别人最多就是怀疑,拿不出证据。
但过几天的闭门听证会是个大坎,
因为需要过会作证。
这个如果作伪证会非常严重。
老黄面对重大抉择:
不承认,作伪证。
万一对手手里有料,那就是刑事责任。
承认,即便是闭门会议,肯定会被对手泄露出去。
所以老黄一合算,就认了。
不过我觉得老黄还是不够滚刀肉,
完全可以等到闭门会议之后,再决定。
在闭门会议上,集中回答国安问题。
然后闭嘴,等下一个热点,这样也许还有转机。
毕竟听证会关心的是国安信息是不是有泄漏而不是到底睡了几次。
显示更多
Prada backpack.
Minimalist, functional and innovative, the Prada backpack distils the essential codes of Prada’s DNA into a timeless design.
Discover more:
#PradaFW26# #Prada#
显示更多


1/ AI 制药正在复刻半导体的“瓶颈交易”。
半导体的需求从 GPU 传导到 HBM、网络、电力和散热;生物医药则沿着:
AI模型 → 设计 → DNA/蛋白 → 检测 → 临床前产能
模型生成越来越便宜,真正稀缺的开始变成湿实验验证。👇
显示更多


1.8 MILLION DNA SAMPLES. ZERO BACKLOG.
When we took over, the FBI Lab was buried under 1.8 million federally collected DNA samples — with roughly 75,000 more coming in every month.
We surged personnel, invested roughly $50 million in upgrades, streamlined the entire pipeline, and put advanced technology and Rapid DNA to work.
Result:
1.8 MILLION samples processed.
Backlog ELIMINATED.
Thousands of investigations already aided.
First time in FBI history.
That means more DNA profiles connecting criminals to evidence, more cases getting solved, and safer streets for American families.
We said we were going to bring results back to the FBI.
-DKP🇺🇸
显示更多


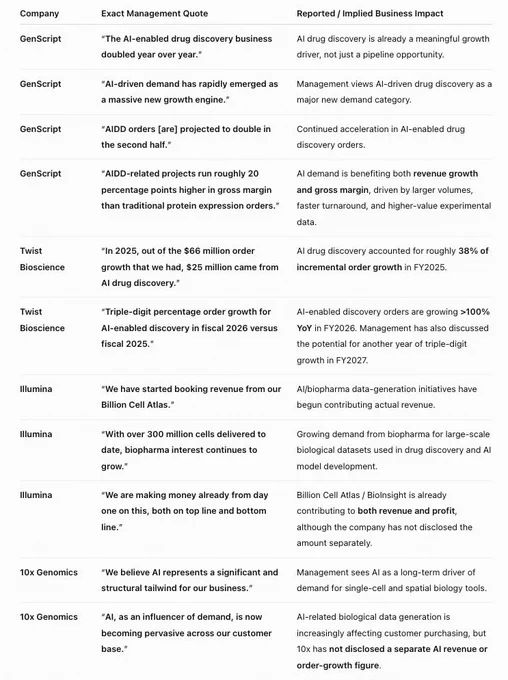
AI Drug Discovery Is Becoming a Bottleneck Trade
I get excited when an industry starts going through a real regime change. AI drug discovery (“AIDD”) increasingly looks like one of those moments.
Two things are happening:
1/ Upstream: the frontier AI labs are piling in.
2/ Downstream: The supply chain is clearly moving.
Supply-chain checks suggest the upstream picks-and-shovels of discovery and early preclinical R&D are starting to feel the increase in experimental volume.
DNA → protein → assays → sequencing → automation → preclinical testing
Names across that stack include $TWST , @GenScript , $ILMN , $TXG , lab-automation vendors and CROs.
$TWST expects triple-digit percentage growth in AI-enabled drug-discovery orders in FY26, and another year of triple-digit order growth in FY27.
@GenScript's AIDD business doubled YoY in 1H26. Its current platform advertises industrial-scale validation of 4,000+ designs/day, with integrated sequence-to-data workflows. Our channel checks suggest the ramp is moving even faster: roughly 8,000 designs/day currently, with a path toward ~16,000/day by YE26.
---
Why does AI drive more wet-lab demand?
1/ AI makes hypothesis generation almost free → way more shots on goal.
The bottleneck is moving from expert-driven design to biological validation.
2/ AI models need continuous experimental feedback — and both good and bad data are useful.
Traditionally, only the highest-conviction A+ candidates might get pushed into expensive validation. With AI, even the B/C candidates can be valuable because failed experiments generate training data.
@GenScript has said its sequence-to-binding workflow can return data in 4–7 days, and that faster cycle times matter because AI models depend on continuous experimental feedback.
@Anthropic is a clean example. @claudeai designed 1,320 protein binders. @adaptyvbio converted those digital sequences into DNA, expressed the proteins and tested binding. Only 354 actually bound. And the 966 failures are not wasted. They are useful negative labels: what does not express, what does not bind, what has poor affinity. Those results help train the next model iteration.
3/ Wet labs are no longer just making drugs. They are making training data.
$TWST / @GenScript increasingly look like biological data foundries.
$TWST explicitly talks about generating model-ready data from AI-designed sequences. In some workflows, the customer may care less about receiving the physical protein than about getting structured experimental results back into the model.
Traditional drug discovery asks: “Does candidate X work?”
AI drug discovery also asks: “What can this experiment teach the model?”
---
TAM of AIDD
If AI is simply a better R&D tool, the relevant spending pool is the $300–400B of annual global pharma R&D. If AI meaningfully increases the number of viable drug programs, the opportunity is larger because it expands downstream demand for DNA synthesis, protein production, assays, and preclinical work.
Near term, we can also size demand from AI-company spending. If Anthropic reaches $80B of ARR in 2026 and spends just 1% on AIDD, that alone would imply ~$800M of annual investment.
---
Trade setup
This is a trade that could have long legs. It’s hard to really stop working until PhaseI/II results (2028+)
It smells a lot like the bottleneck trade we just saw in semis: GPUs → HBM → networking → power/cooling. In biology, It basically follows the drug discovery process downstream: AI models → designs → DNA/protein → assays → preclinical capacity.
After the upstream picks-and-shovels, animal testing could become the next bottleneck. Monkey prices are already near prior highs and CRO capacity is tight. AIDD pushing more candidates into preclinical development would only add demand.
?? But clinical trials are still the bottleneck?
This is the biggest pushback I keep coming back to. No matter how fast discovery becomes, drugs still need to go through preclinical → Phase I → Phase II → Phase III → approval. You still need patients, time and capital.
But that doesn’t mean the bottleneck trade won’t work. More viable candidates — especially with higher success rates — still means more demand throughout the development process.
And who knows: clinical trials themselves may eventually be optimized by AI.
?? What breaks the trade?
Near term, the picks-and-shovels trade breaks if experimental budgets stop growing, AI-generated designs don’t translate into useful wet-lab hits, or capacity catches up too quickly.
Longer term, the thesis breaks if AI drugs look great in discovery / Phase I but fail at normal rates in Phase II/III. That is why Phase II matters so much.
?? Milestones
Late 2026–2027: first Isomorphic-designed drugs enter human trials; more AI-native programs move into IND-enabling work / tox.
2028–2030: clinical trial results start telling us whether AI-designed drugs actually perform better than conventional drugs.
Calling all the "bottleneck bros". :) @jukan05 @zephyr_z9 @aleabitoreddit @ParadisLabs
+++
More comprehensive analysis:
显示更多